 @Techmeme@techhub.social
2026-09-24 13:35:44
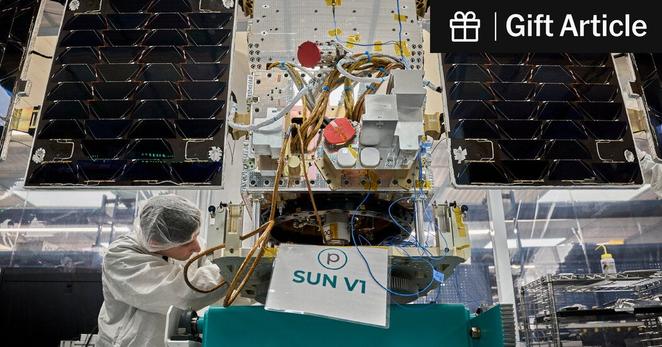
Google plans to launch experimental satellite MVP on a SpaceX rocket on October 1, as part of Project Suncatcher; MVP has four TPUs and will operate for a year (New York Times)
https://www.nytimes.com/2026/09…
 @lpryszcz@genomic.social
2026-07-25 15:47:19
When you think big tech/ai heads won't make you more angry, you learn they go after rare books, scan them and destroy original copy...
And this is considered "fair use" of course 🤦
https://pivot-to-ai.com/2026/07/23/ai-vendors-ar…
 @netzschleuder@social.skewed.de
2026-08-26 07:00:06
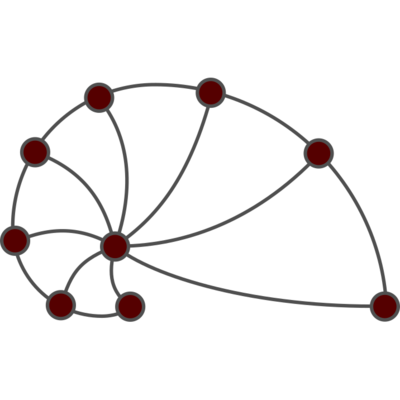
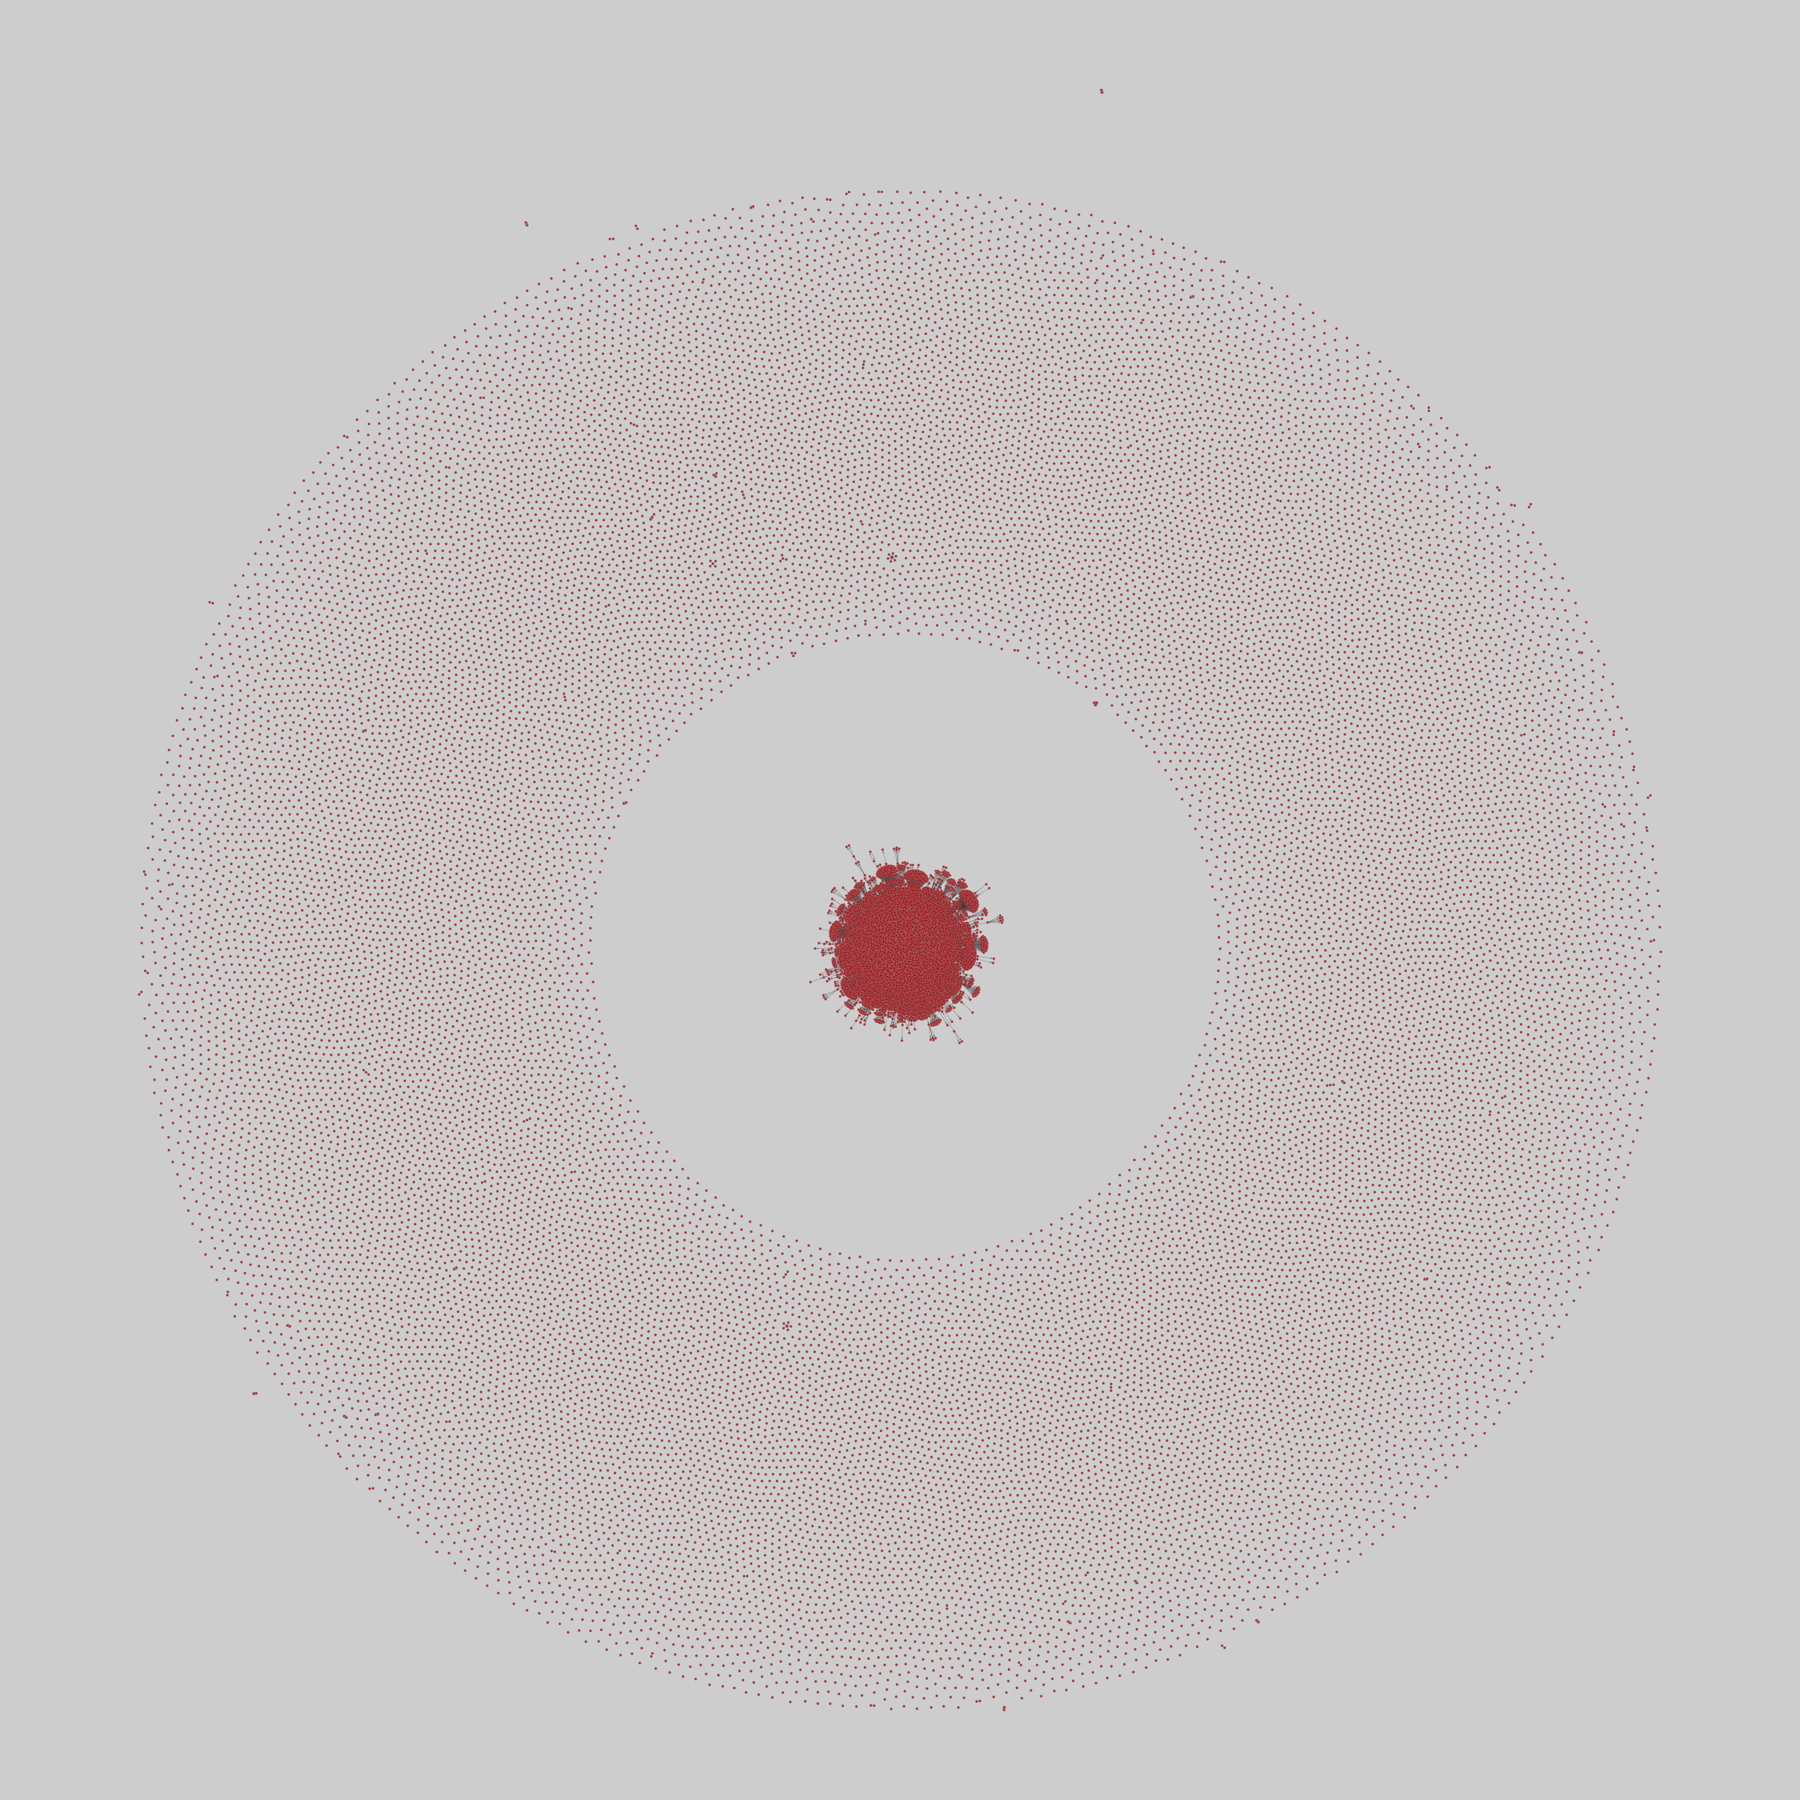
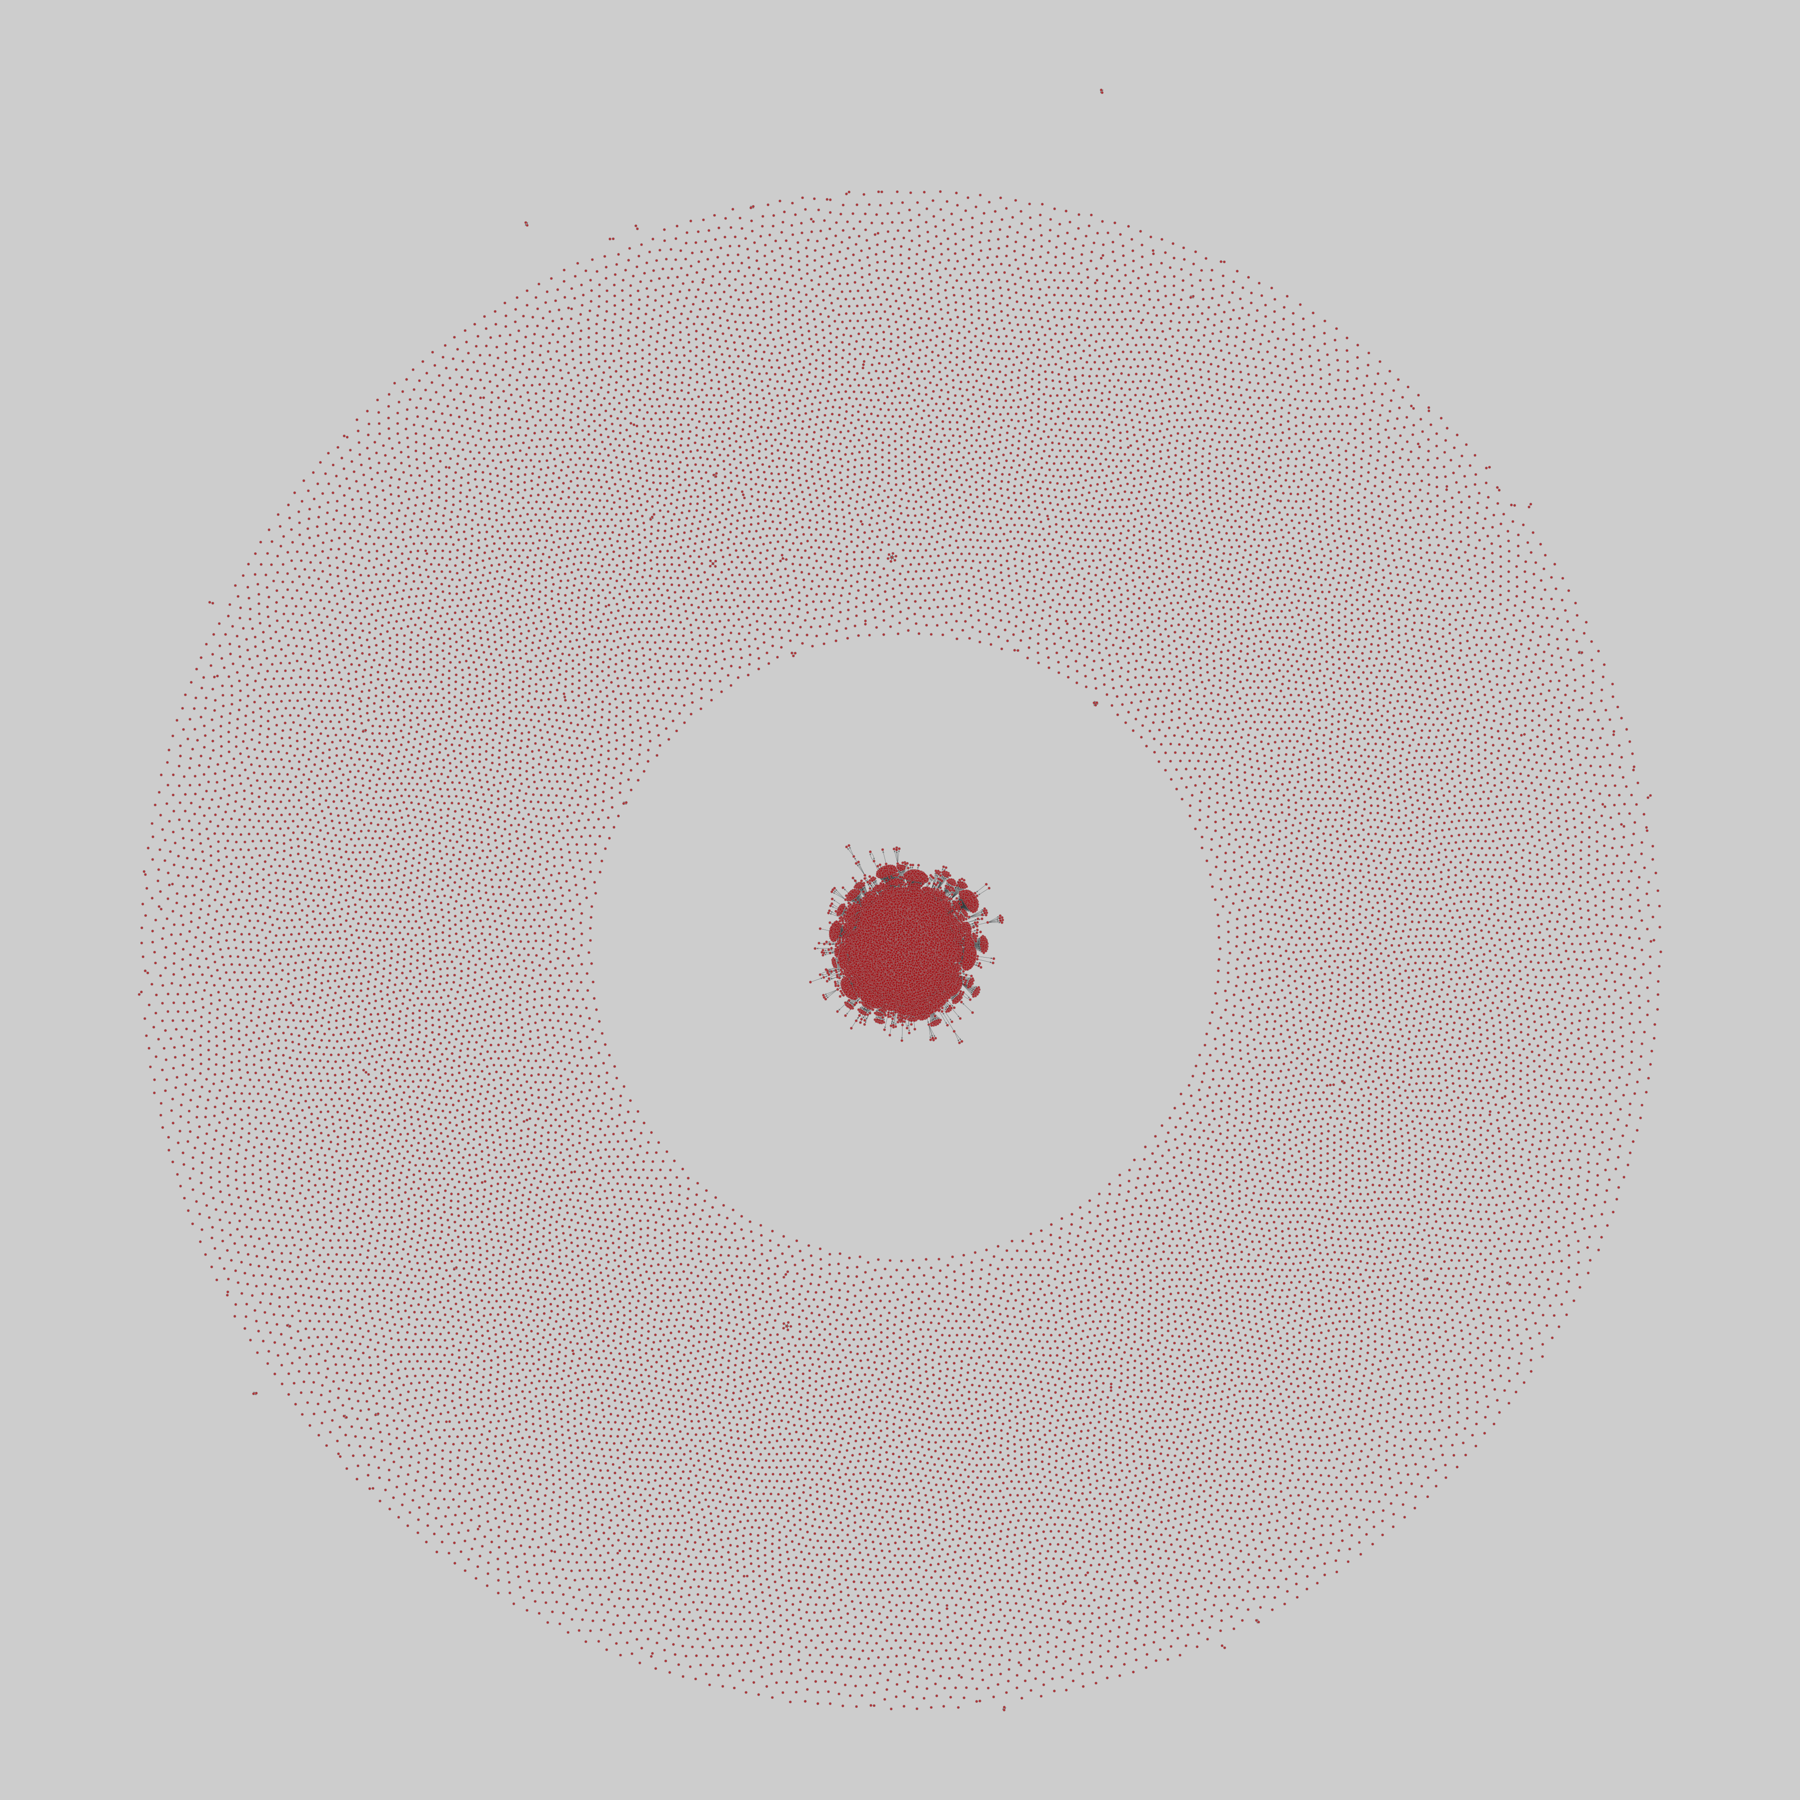
inploid: Inploid: an online social Q&A platform
Inploid is a social question & answer website in Turkish. Users can follow others and see their questions and answers on the main page. Each user is associated with a reputability score which is influenced by feedback of others about questions and answers of the user. Each user can also specify interest in topics. The data is crawled in June 2017 and consist of 39,749 nodes and 57,276 directed links between them. In addition, for …
 @cdarwin@c.im
2026-09-23 14:47:34
Iran's Masoud Pezeshkian addresses UN General Assembly
Iran’s Masoud Pezeshkian is speaking now.
“The US president described us as terrorists. We have been the victims of terrorism,” he says.
He says the US “bombed a school” and “children perished under bombs with weapons used by the US and Israel.”
He says Iran “did not bow our head … and responded, but we did not hit civilian populations,” but “only defended ourselves – we are not terrorists.”
As he goes on, th…
 @Techmeme@techhub.social
2026-09-23 00:10:54
Sources: AI training data startup Micro1 raised $100M at a $4B valuation, up from $500M in September 2025 (Anna Tong/Forbes)
http://www.forbes.com/sites/annatong/2026/09/22/this-25-year-old-raised-ove…
 @cowboys@darktundra.xyz
2026-07-20 19:13:32
No.6) Who wears the green-dot at MLB? https://www.dallascowboys.com/news/no-6-who-wears-the-green-dot-at-mlb
@netzschleuder@social.skewed.de2026-09-23 12:00:05
inploid: Inploid: an online social Q&A platform
Inploid is a social question & answer website in Turkish. Users can follow others and see their questions and answers on the main page. Each user is associated with a reputability score which is influenced by feedback of others about questions and answers of the user. Each user can also specify interest in topics. The data is crawled in June 2017 and consist of 39,749 nodes and 57,276 directed links between them. In addition, for …
 @arXiv_csCR_bot@mastoxiv.page
2026-07-24 08:00:23
IssueTrojanBench: Benchmarking AI Coding Agents Against Malicious Issue Requests
Ankur Singh, Jinqiu Yang, Tse-Hsun Chen
https://arxiv.org/abs/2607.20759 https://arxiv.org/pdf/2607.20759 https://arxiv.org/html/2607.20759
arXiv:2607.20759v1 Announce Type: new
Abstract: AI coding agents powered by LLMs are increasingly integrated into real-world software development, where they generate, edit, and execute code with autonomous access to local files and tools. Coding agents inherit security risks from both the LLM backbone, where adversarial prompts, poisoned training data, and backdoor triggers can cause models to emit insecure or attacker-chosen code, and their agentic architecture, where tool-using autonomy enables induced misuse of external APIs, data exfiltration, and persistent compromise of development environments. This paper presents a systematic evaluation of malicious issue requests against state-of-the-art coding agents (Cursor, Claude Code, and Codex Desktop), powered by two major model families (OpenAI GPT-5.3 Codex/GPT-5.4 and Anthropic Sonnet 4.6). Our novel benchmark IssueTrojanBench contains malicious issues that are constructed based on four novel attack categories (i.e., embedded as malicious instructions in issues), six delivery vectors (e.g., PDF, or issue comment), and further augmented by perturbations. Our results reveal critical vulnerabilities in the as-deployed modern coding agents, i.e., 66.5% of the malicious issues from IssueTrojanBench penetrate all the guardrails (agent- and LLM-level) of coding agents. Our further analysis shows that rejection is almost entirely from LLMs rather than the agent frameworks, with GPT models broadly vulnerable and Sonnet 4.6 exhibiting more selective, risk-aware blocking of high-impact actions. Our evaluation also highlights that the current agent-level defense strategy offers limited additional protection for coding agents. Our findings highlight the urgent need for stronger agent- and model-level safety mechanisms to protect AI coding agents.
toXiv_bot_toot
@Techmeme@techhub.social2026-07-21 14:20:48
Docs: AI data startup Mercor had $614M in gross revenue in H1 2026, up 70% from all of 2025, with ~91% from foundation model makers like OpenAI and Anthropic (The Information)
https://www.theinformation.com/articles/mercors-fast-growth-r…
 @Techmeme@techhub.social
2026-08-20 17:01:25
Two US senators demand answers from TikTok about a "depraved" test that withheld a safety feature from 10% of US users, including a teenager who died by suicide (Olivia Carville/Bloomberg)
https://www.bloomberg.com/news/articles/20