 @primonatura@mstdn.social
2026-09-15 16:00:49
 @leftsidestory@mstdn.social
2026-06-28 00:30:02
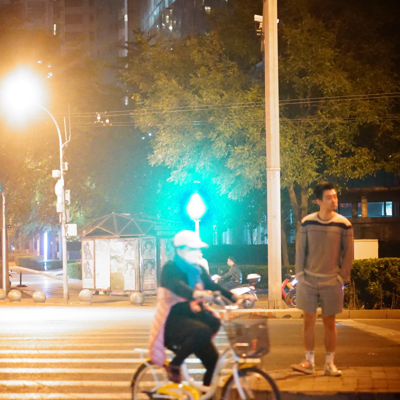
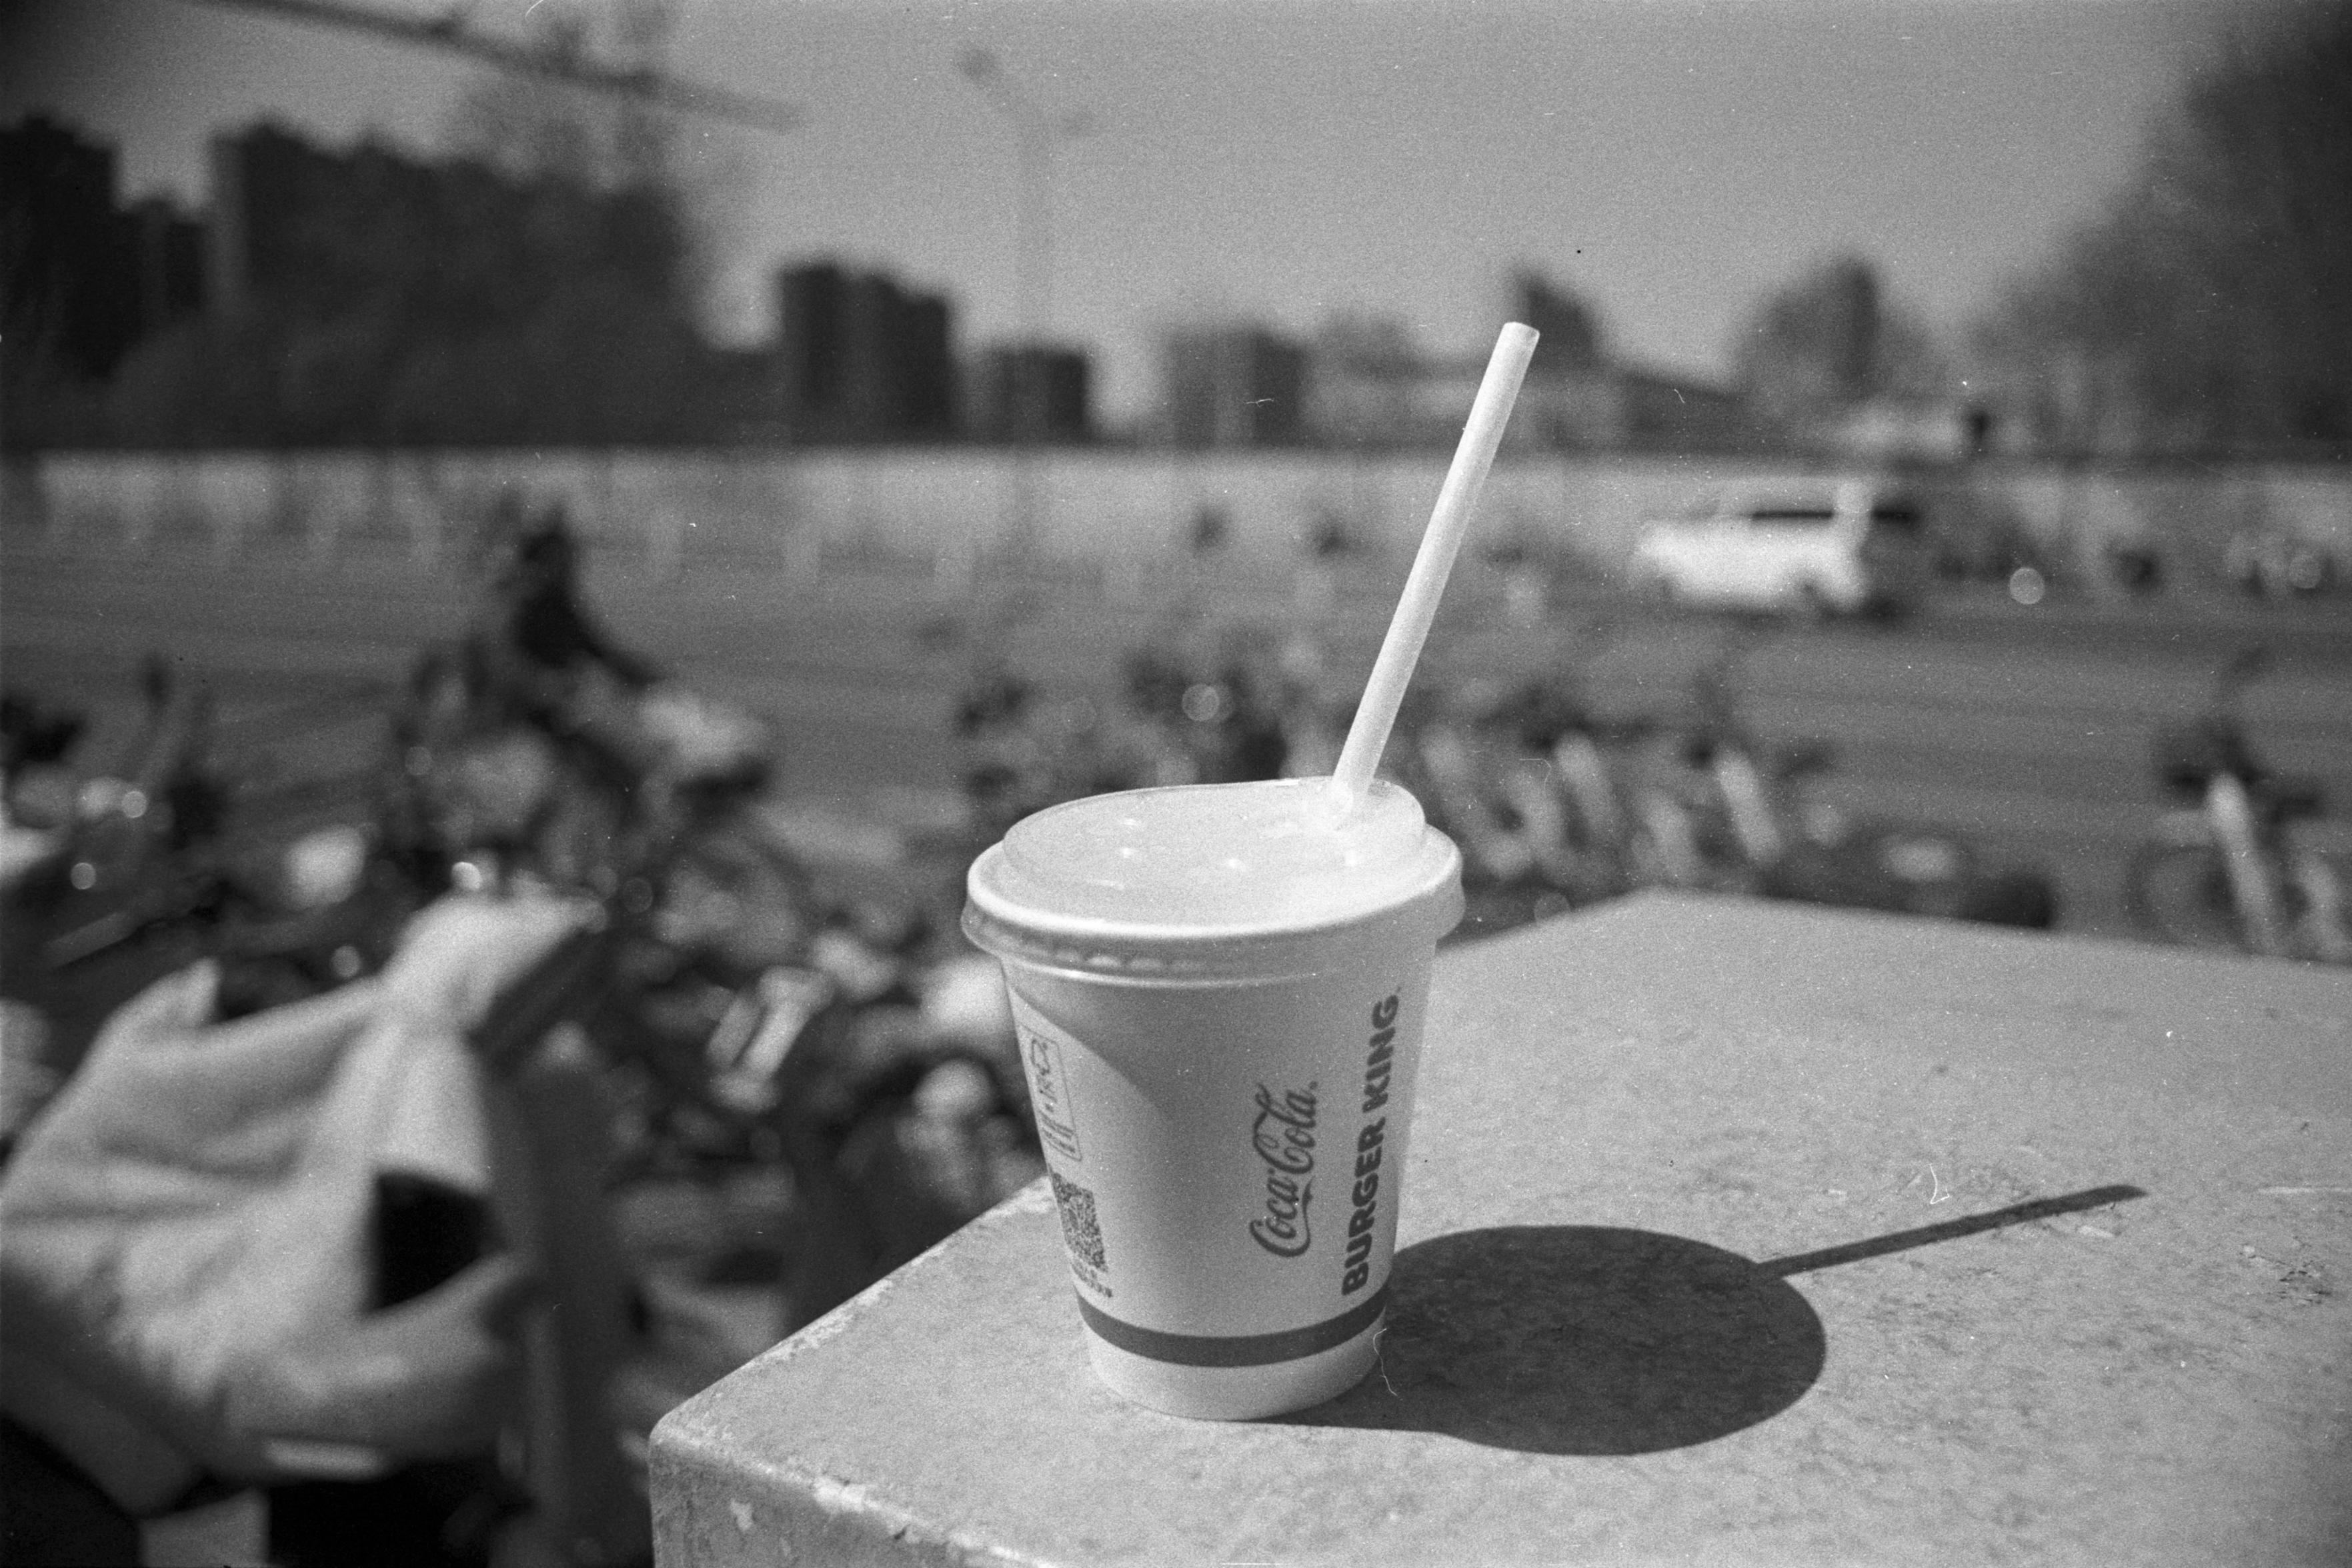
The Indifference of Modernity 📸
无关紧要的现代性 📸
📷 Pentax MX
🎞️ Ilford FP4 Plus 125 (FF), expired 1994
If you like my work, Support by buying me a coffee or a roll of film from
PayPal https://www.paypal.com/paypalme/ydcdingsite
Wise
 @harrysentonbury@social.linux.pizza
2026-09-12 23:15:26
goodnight
#night #spookySaturday #shittember
 @arXiv_csHC_bot@mastoxiv.page
2026-08-12 08:22:14
MazzikaAI: A knowledge-based performance-to-prompt compiler for real-time Arabic maqam accompaniment with a streaming text-to-music model
Jiaxin Du, Boulbaba Abdeljaouad, Yong Zhuang, Haoyu Li
https://arxiv.org/abs/2608.10360 https://arxiv.org/pdf/2608.10360 https://arxiv.org/html/2608.10360
arXiv:2608.10360v1 Announce Type: new
Abstract: Arabic maqam music microtonal, modal, and built on ornamented call and response is among the traditions most underserved by generative music models, whose training frameworks remain predominantly Western and equaltempered. Real time accompaniment sharpens this gap: an AI partner must listen, adapt dynamically, and respect idiomatic microtonal structures. Streaming text to music models provide strong generative capabilities but lack precise control interfaces. We present MazzikaAI, a knowledge based system that uses natural language as the actuator of a realtime control loop. By compiling live MIDI, gesture, and inferred harmony into continuously updated text prompts, MazzikaAI steers an unmodified streaming generator, Google Lyria RealTime, without requiring model finetuning. The system embeds expert knowledge of six core maqamat, characteristic ornaments, and ensemble dynamics, maintaining realtime responsiveness with subsecond keytoaudibleupdate latency. Empirical evaluations demonstrate that dynamic prompt compilation reliably grounds generation in microtonal scales, significantly increasing offgrid quartertone content over baseline generation. Beyond its core implementation, MazzikaAI illustrates how deterministic knowledgebased rules can effectively bridge expert, nonWestern musical traditions and unfinetuned foundation models. This architecture establishes a scalable paradigm for realtime humanAI cocreation, offering a generalizable blueprint for interactive accompaniment, adaptive music education, and culturally inclusive generative audio across diverse global idioms.
toXiv_bot_toot
 @Techmeme@techhub.social
2026-08-05 15:55:59
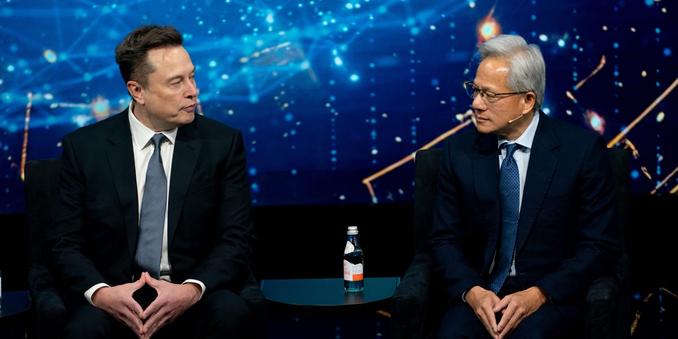
Elon Musk says SpaceX has decided to "build exclusively on Nvidia because we think the Vera Rubin architecture is the best architecture" (Shubhangi Goel/Business Insider)
https://www.businessinsider.com/elon-musk-spacex-will-only-buy-from-nvidia-20…
 @arXiv_csAR_bot@mastoxiv.page
2026-08-14 07:32:47
Why Do Prefetchers Fail? Let Agents Answer
Xiangfeng Sun, Ceyu Xu, Ningzhi Ai, Zeyu Zhu, Yiyang Yuan, Yuan Xie
https://arxiv.org/abs/2608.13027 https://arxiv.org/pdf/2608.13027 https://arxiv.org/html/2608.13027
arXiv:2608.13027v1 Announce Type: new
Abstract: Hardware prefetchers are crucial to processor performance, yet their design remains labor-intensive and expert-driven. Architects inspect execution and memory-access traces, identify patterns, translate them into online hardware heuristics, and evaluate them in simulation, often with no guarantee of improvement. Human experts cannot systematically inspect billion-instruction traces across diverse real-world workloads.
We present a performance-anomaly-driven autoresearch flow that repeatedly asks why a deployed prefetcher fails and uses the diagnoses to construct the Mixture of Prefetchers (MoP). Each iteration localizes high-impact unexplained misses to program counters, gives agents hardware logs, source code, and sliced traces, validates diagnoses through runnable minimal cases, and synthesizes specialized sub-prefetchers for recurring pattern families. Measured performance and remaining anomalies feed subsequent iterations, enabling simulator-in-the-loop discovery beyond model priors.
The campaign consumes 1.91 billion DeepSeek V4 Pro tokens. On SPEC CPU2006 and SPEC CPU2017, MoP achieves a 61.1% geomean IPC speedup over no prefetching, outperforming the human-designed Alecto, Berti, and Pythia prefetchers by 14.5%, 21.6%, and 23.6%, respectively. RTL synthesis in a 6nm library reports 110 KB of on-chip storage and 0.0347 mm^2 area. To our knowledge, this is the first empirical demonstration that an agent-driven hardware-design process can produce an RTL-practical prefetcher that outperforms state-of-the-art human designs on unseen workloads.
toXiv_bot_toot
 @ruth_mottram@fediscience.org
2026-06-18 05:36:22
And here is the video and short summary for those wanting the TL;DR
https://www.frontiersin.org/journals/science/article-hubs/polar-geoengineering-risks-realities/explainer
https://fediscience.org/@Ruth_Mottram/116769474882730548
Ruth_Mottram - We also wrote a version for kids:
https://kids.frontiersin.org/articles/10.3389/frym.2025.1633572
https://fediscience.org/@Ruth_Mottram/116769466126905589
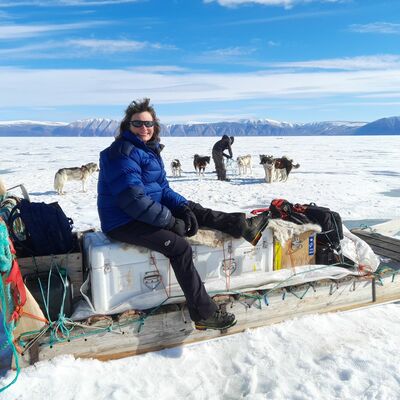
Ruth_Mottram - Flurry of articles, including in the Guardian on the very well funded but seriously misguided efforts to geoengineer the Arctic by growing sea ice, reminds me that it is probably time to report our critical article on the subject..
https://www.frontiersin.org/journals/science/articles/10.3389/fsci.2025.1527393/full
 @cdarwin@c.im
2026-07-06 18:39:29
 @arXiv_csHC_bot@mastoxiv.page
2026-08-12 08:22:32
Visual-to-Haptic Augmentation in XR: A Wearable Glove for Perceptual Grounding in Multimodal Interaction
Faisal Mohd, Hamdi Elsaddik, Erhan Baturay Onural, Jihong Zhang, Fedwa Laamarti, Abdulmotaleb El Saddik
https://arxiv.org/abs/2608.10368 https://arxiv.org/pdf/2608.10368 https://arxiv.org/html/2608.10368
arXiv:2608.10368v1 Announce Type: new
Abstract: Extended Reality (XR) systems increasingly deliver high-fidelity visual and auditory experiences, yet tactile perception remains comparatively underutilized as a modality for enriching embodied interaction. This work presents a visual-to-haptic wearable glove and a feature-based visual-to-haptic mapping algorithm that translates spatial and temporal visual features from images and videos into distributed vibrotactile patterns. The proposed method extracts motion, edge, and brightness cues and fuses them into actuator-level intensity maps aligned with a 29-actuator glove arranged in a five-by-seven layout.
The system is implemented through a modular four-layer architecture comprising the XR environment, media content handling, visual-to-haptic processing, and embedded haptic hardware. A within-subject user study (N = 20) compared visual-only interaction with visual-plus-haptic augmentation across texture-based and dynamic video scenarios. Results indicate that tactile augmentation significantly improves perceived realism in dynamic video scenarios and enhances immersion and visual-tactile correspondence across conditions, with stronger and more consistent effects observed for dynamic visual events.
While the current implementation operates in a single-user, offline-synchronized configuration, the findings demonstrate that vision-driven tactile augmentation can function as a perceptual enhancement layer within multimodal XR systems. Such a layer may provide a foundation for future socially enriched XR environments where coherent multisensory grounding supports higher-level interaction and communication.
toXiv_bot_toot