 @simon_brooke@mastodon.scot
2026-08-12 12:14:22
Right, my #Clojure humidity library now computes all the values that I think it should. The code could do with a bit of tidying up, there is no data validation, I have no reliable test data for the actual-vapour-pressure function, and I can't yet do the time-shifting computations I want; but nevertheless I think this is now usable and useful.

 @arXiv_qbioOT_bot@mastoxiv.page
2026-07-21 07:56:08
Orientation Reading by Production Vision-Language Models on Optotype Charts: A Controlled Multi-Model Evaluation Across Reasoning Modes, Prompts, and Access Modalities
Shahryar Wasif, Avneek Sandhu, Bin Hu
https://arxiv.org/abs/2607.16595 https://arxiv.org/pdf/2607.16595 https://arxiv.org/html/2607.16595
arXiv:2607.16595v1 Announce Type: new
Abstract: OBJECTIVES: Vision-language models are increasingly used to interpret medical and everyday images through consumer chat interfaces, yet their ability to read orientation - the single perceptual operation tested by the tumbling-E acuity optotype - is poorly characterized on the surfaces through which they are actually used. METHODS: We evaluated four production vision-language models (referred to as Claude, GPT, GROK, and Gemini) through their consumer chat interfaces on a locked set of seven optotype charts: four uniform tumbling-E charts (one per cardinal orientation), two mixed-orientation tumbling-E charts, and one Snellen letter chart as a specificity control. Each model was run in two reasoning modes (Fast and Thinking) under two prompt variants (with and without an explicit orientation-decoding rule) by up to three operators. The corpus comprised 920 scoreable trials and 50,420 glyph judgements. The primary outcome was glyph-level accuracy against the chart's designed orientation, summarized with Wilson 95% confidence intervals. RESULTS: Accuracy ranged from 43.0% to 97.0% across models on identical charts, and the strongest model depended on reasoning mode (GPT 97.0% in Fast mode; GROK 96.6% in Thinking mode). Errors were not random but collapsed onto a model-specific attractor direction. Models were 96-100% internally self-consistent yet ranged widely in accuracy, dissociating reliability from validity. An answer-key-free ensemble-consensus estimate tracked accuracy closely (r = 0.998). For one model, consumer-interface accuracy fell 25-27 points below programmatic access, almost entirely on a single orientation. CONCLUSIONS: A single accuracy figure conceals clinically relevant, orientation-specific failure modes; vision-language models should be evaluated along multiple axes and on the deployment surface before image-interpretation outputs are trusted.
toXiv_bot_toot
 @UP8@mastodon.social
2026-09-10 01:01:52
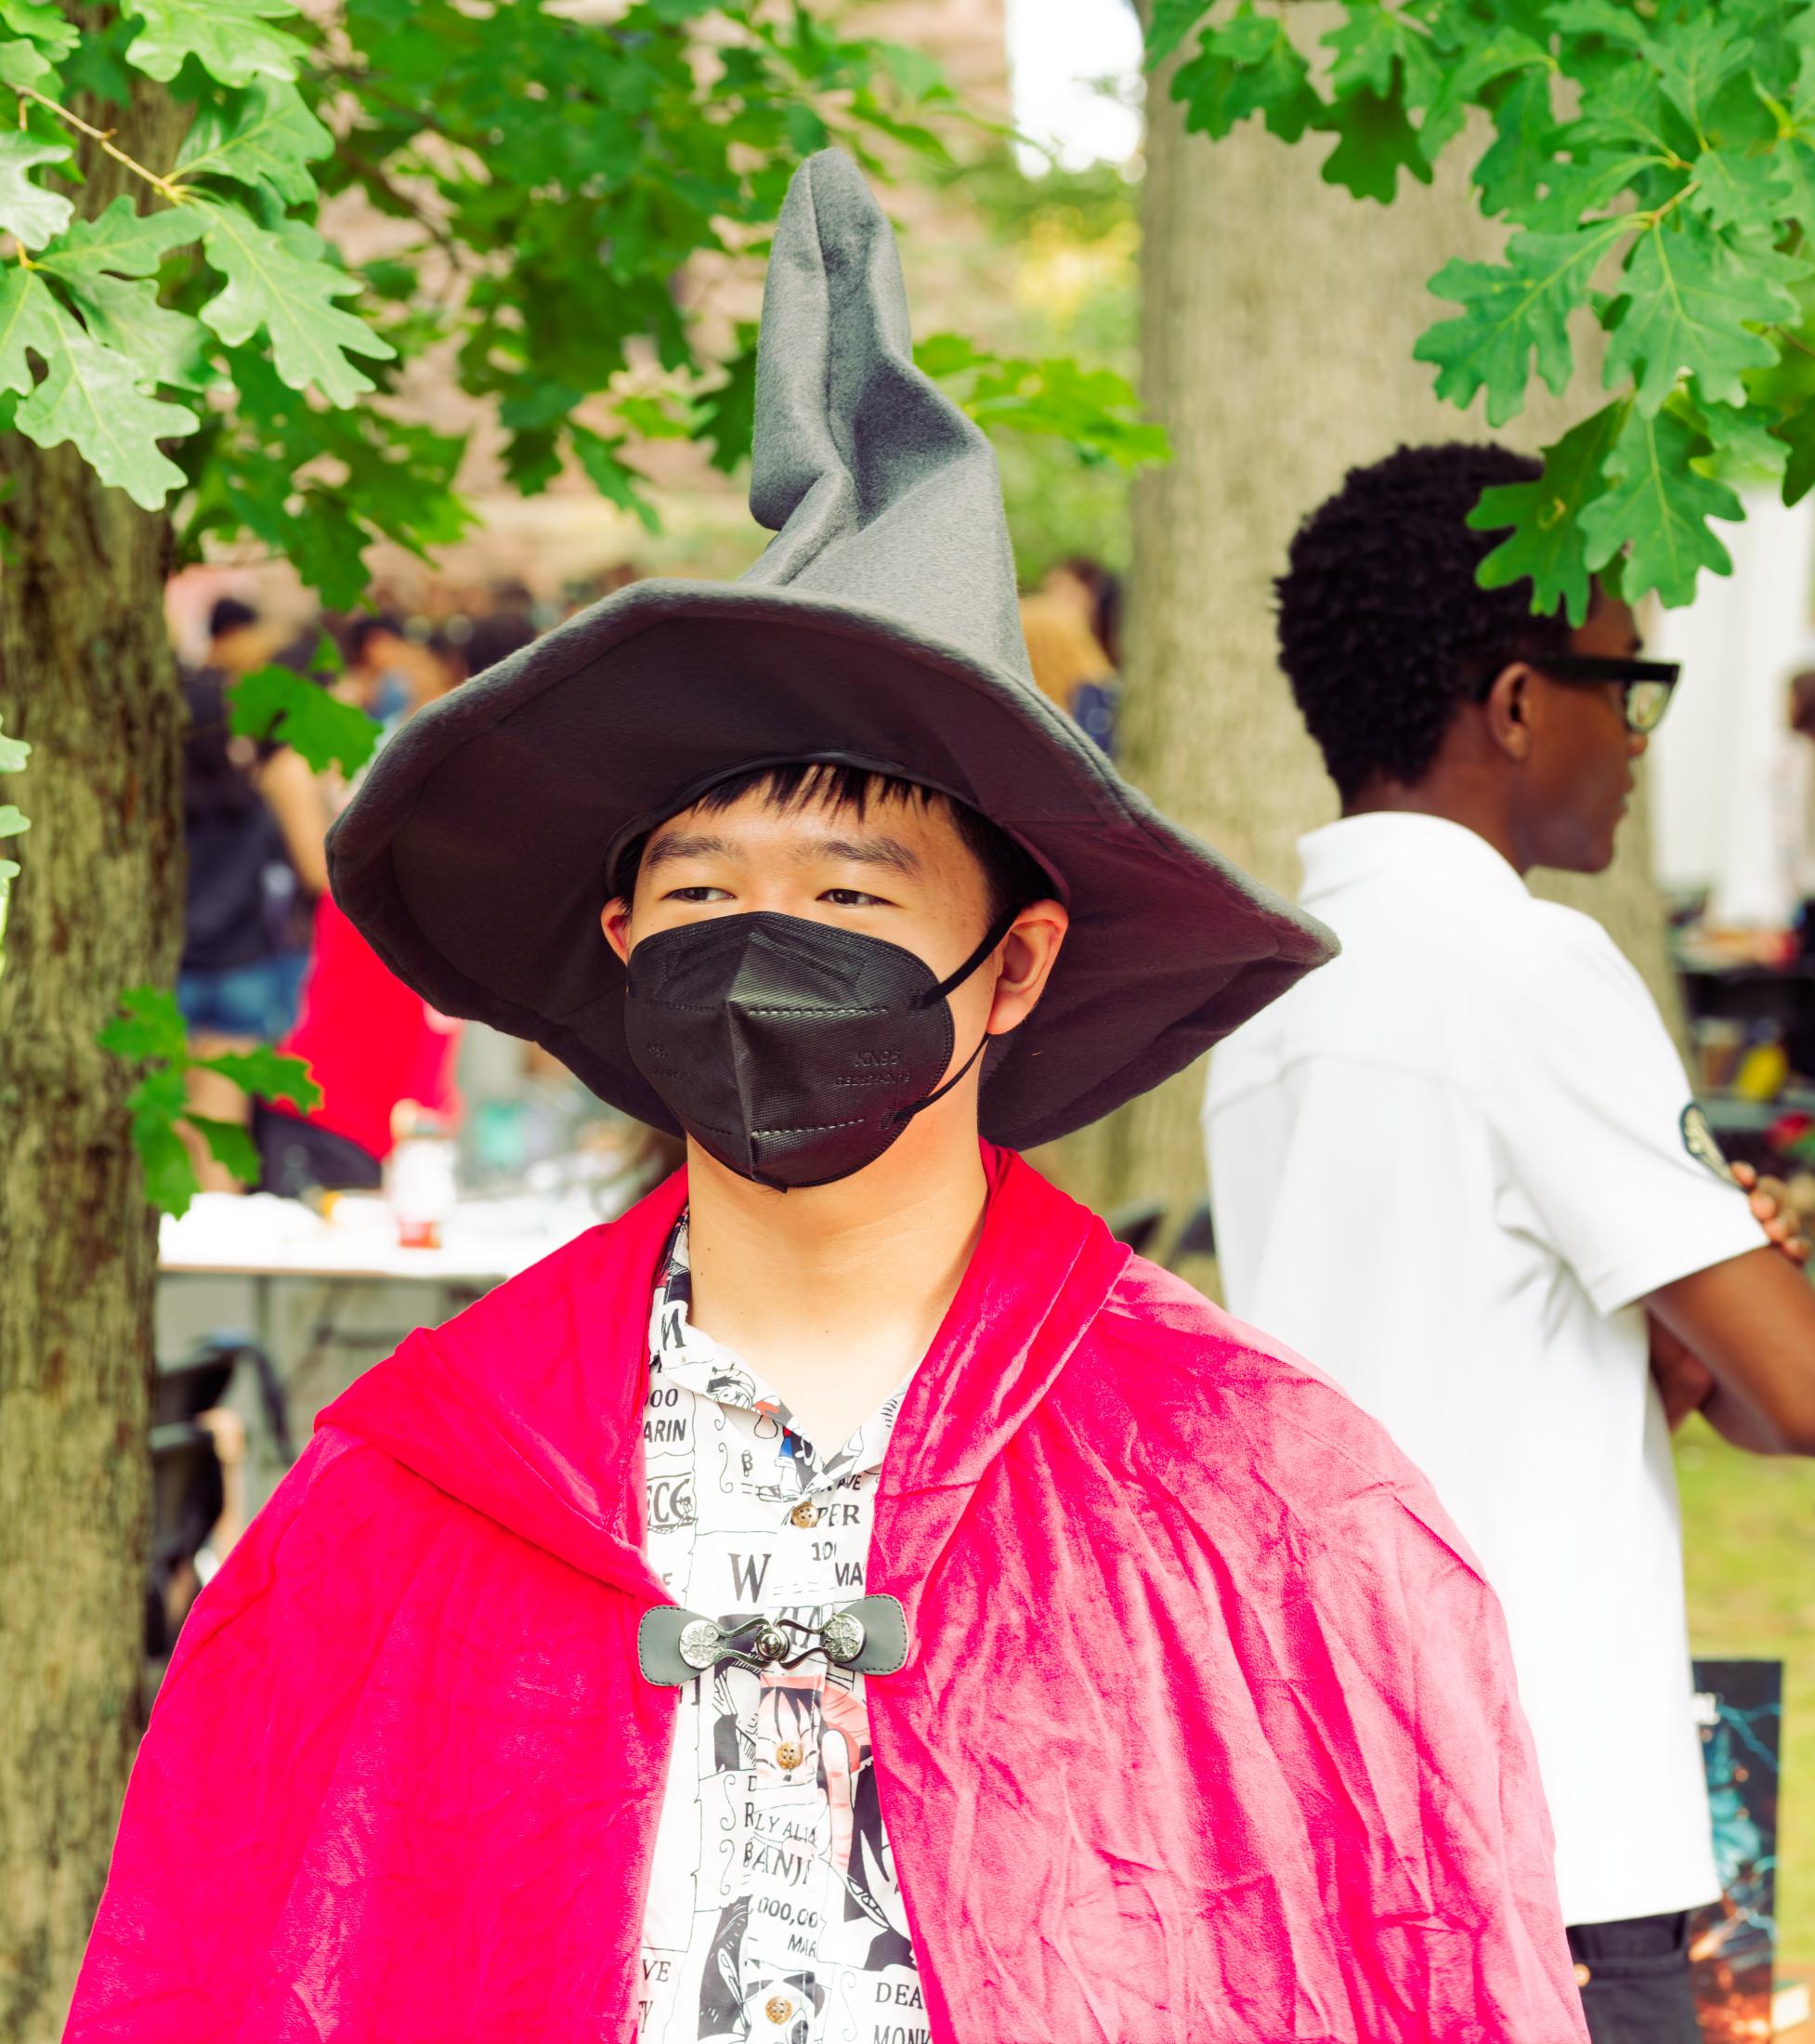
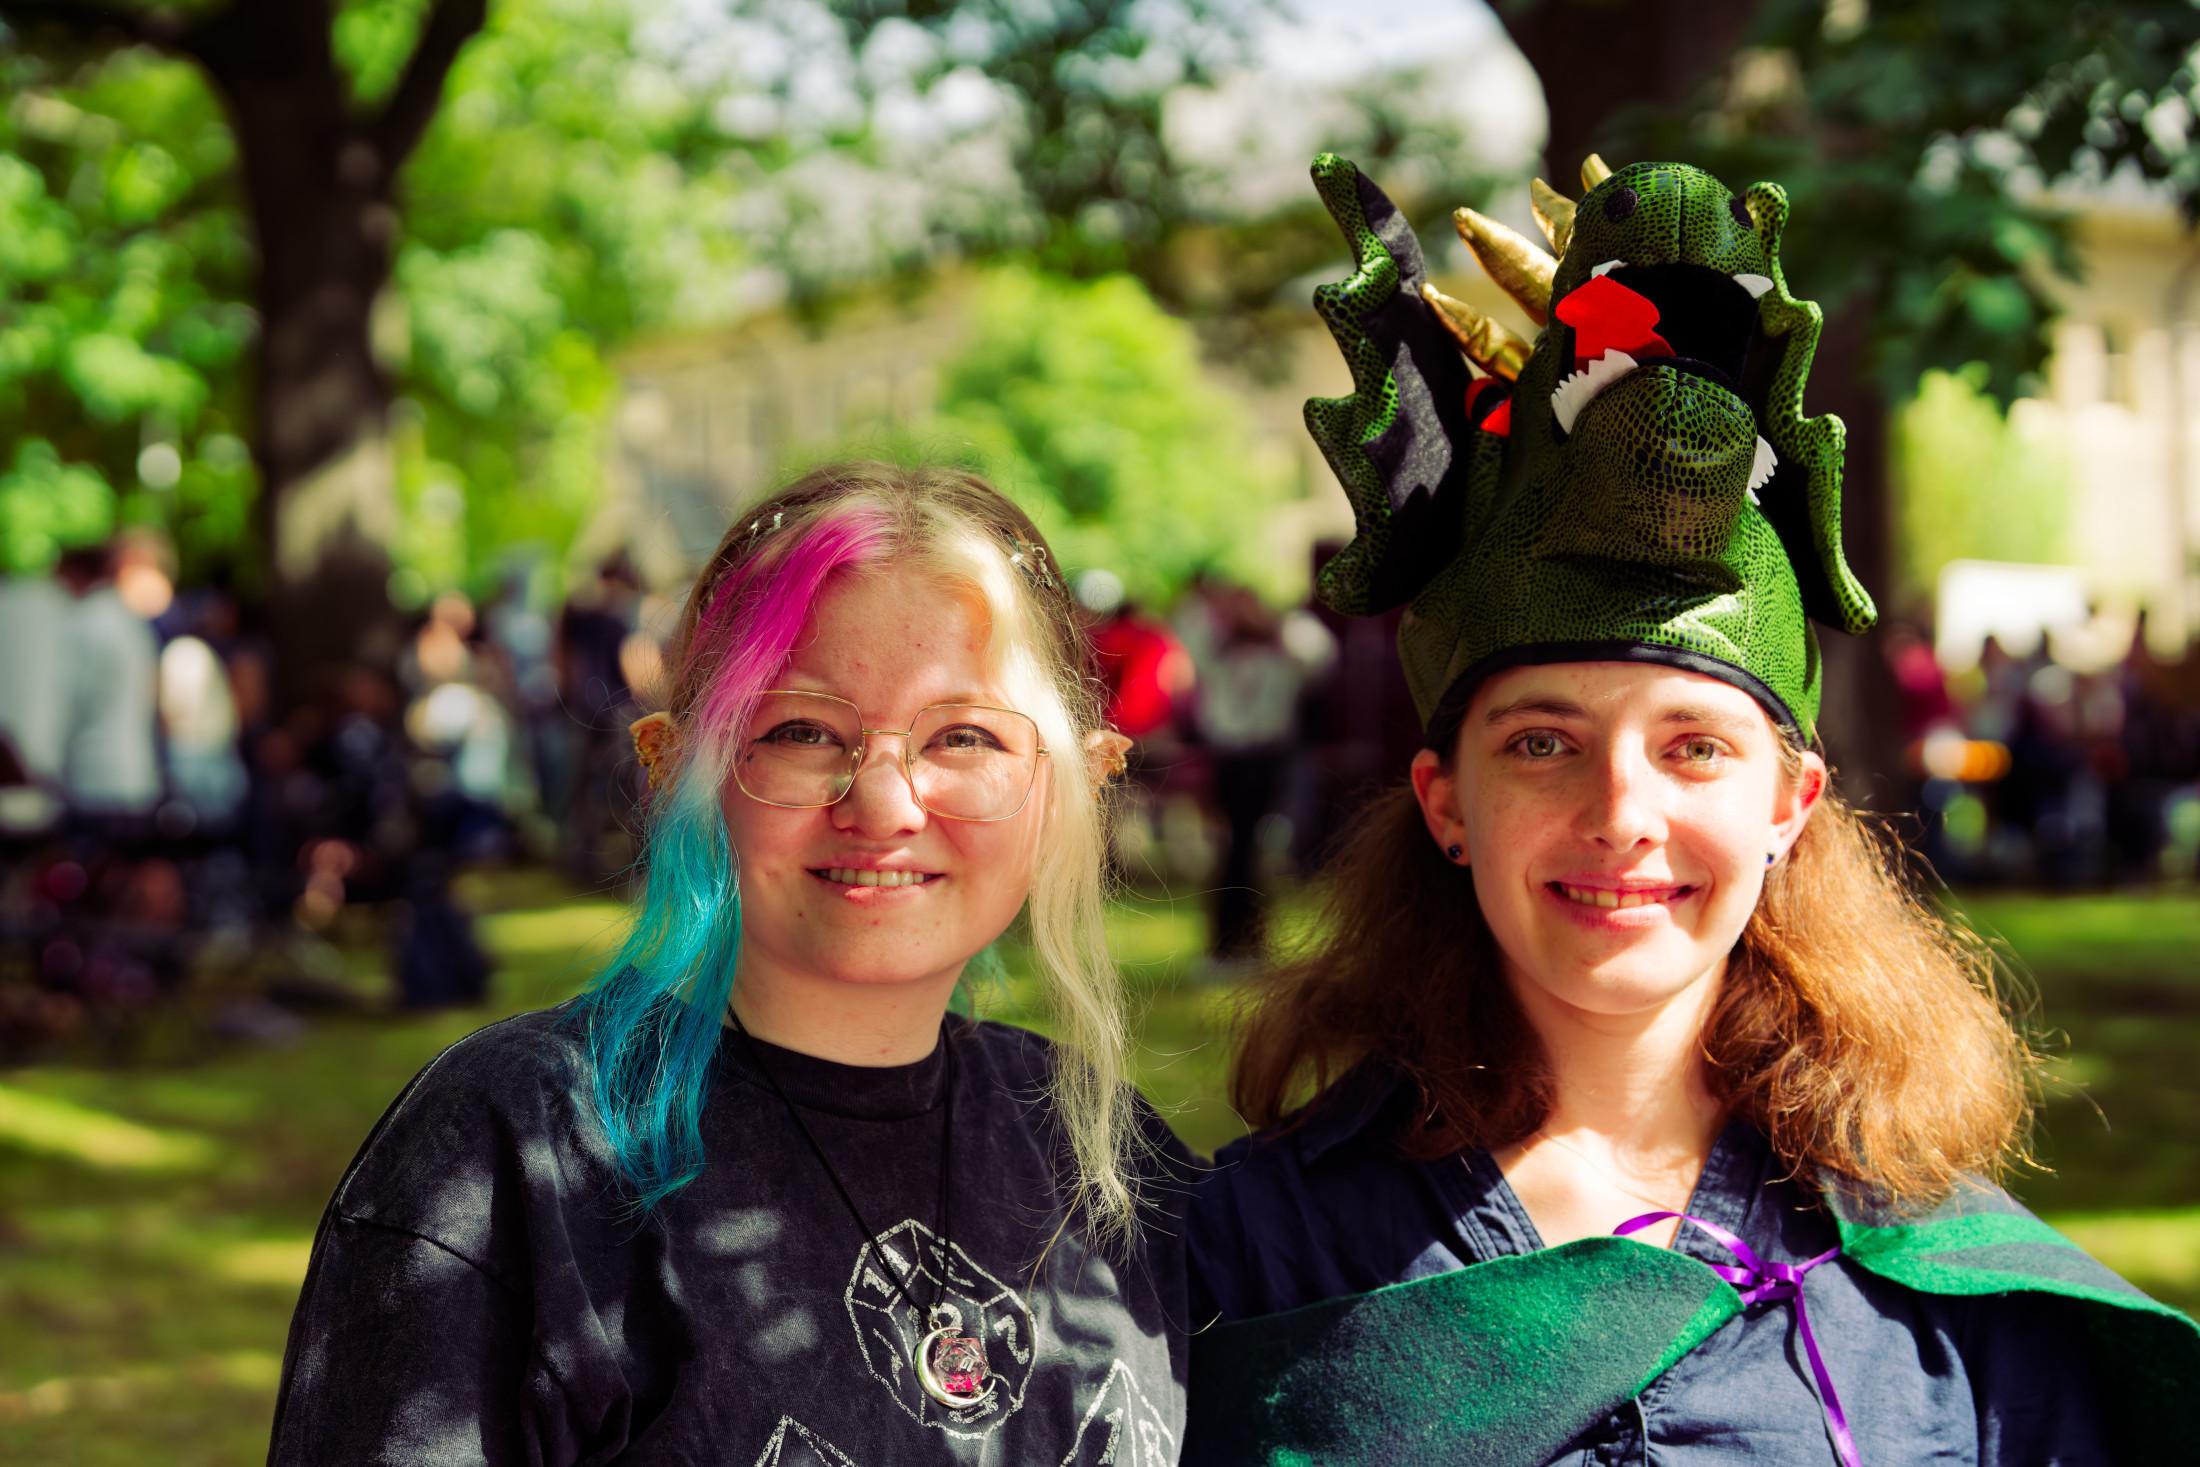
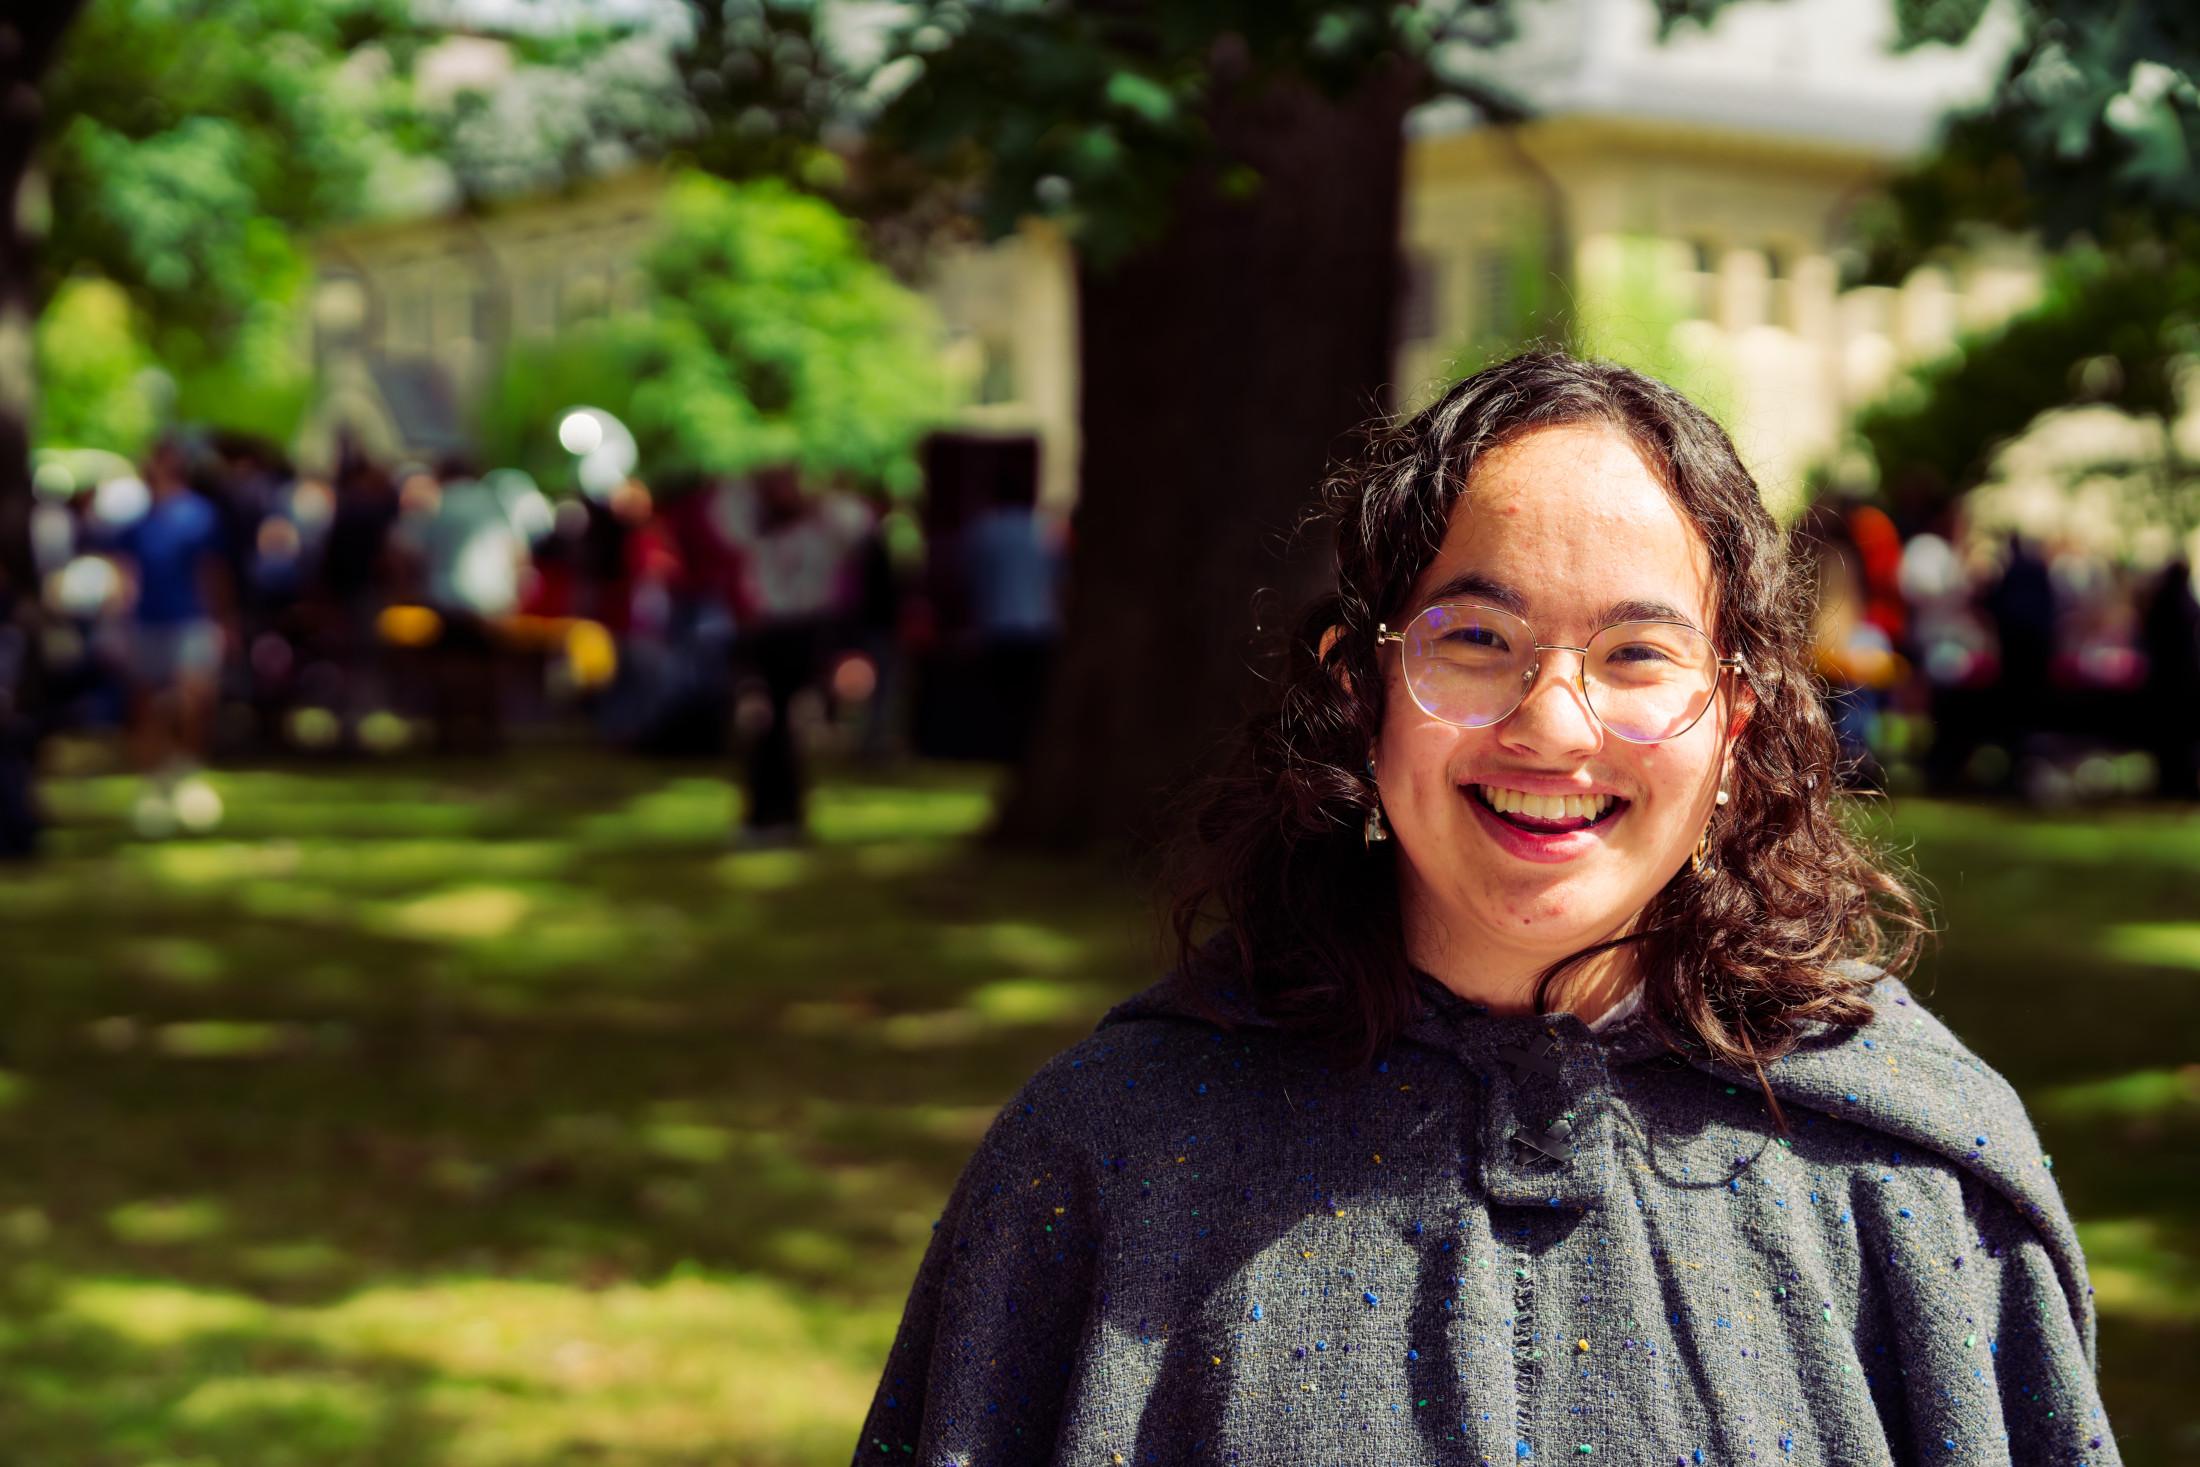
More members of the Dungeons and Dragons club, who did not need a user's manual for the fox-photographer
#photo #photography #groupportrait #dungeonsanddragons #cornell #clubfest #ithaca #cosplay #roleplay
 @UP8@mastodon.social
2026-09-10 00:52:14
 @UP8@mastodon.social
2026-09-10 00:56:33