 @Techmeme@techhub.social
2026-08-21 22:45:54
Gurman: as part of Vision Pro cuts, Apple is largely shutting down a team focused on gaming and reducing the size of a unit producing immersive video content (Chance Miller/9to5Mac)
https://9to5mac.com/2026/08/21/apple-lays-off-200-people-across-vis…
 @CubitOom@social.linux.pizza
2026-07-22 22:04:02
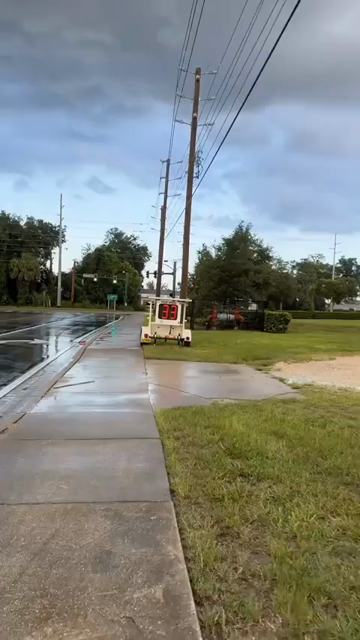
They are hiding mobile Flock Cameras now
Video Source:
#surveillance
 @penguin42@mastodon.org.uk
2026-07-22 01:19:24
This styropro video with triboelectric light effects in a vacuum is very very very neat:
https://www.youtube.com/watch?v=0Y-9GbsS9Fg
@Techmeme@techhub.social2026-08-21 19:07:38
Sources: Apple is cutting 200 jobs, including ~100 positions from the Vision Pro unit and another 100 from the Siri team, as it focuses on new devices and AI (Mark Gurman/Bloomberg)
https://www.bloomberg.com/news/articles/20
 @niklaskorz@rheinneckar.social
2026-07-19 17:58:34
Ah yes, DHH is certainly who we should look towards for how to govern the NixOS foundation. /s
This blog post is the wildest shit I had to read in a while.
https://fzakaria.com/2026/07/18/how-to-piss-off-your-nix-friends

 @seeingwithsound@mas.to
2026-07-18 16:09:10
It's now well over 2 months after the third blind person received an ICVP brain implant for restoring vision. How is she doing? Here are video clips of ICVP recipient Chyvonne Wilson Blanchard in her first days of training https://www.facebook.com/chyvonne.blanchard/owner_reels

 @Dragofix@veganism.social
2026-08-31 22:03:47
MEPs With Agri-Food Financial Stakes Vote Against Environmental Rules, Study Finds https://vegconomist.com/politics-law/meps-agri-food-financial-stakes-vote-against-environmental-rules-study-finds/
 @arXiv_qbioNC_bot@mastoxiv.page
2026-07-22 07:57:40
Eccentricity-Constrained CNN Training Reveals Adaptive Information Coding Around the Visual Field
Dylan M. Diaz, Margaret M. Henderson
https://arxiv.org/abs/2607.19316 https://arxiv.org/pdf/2607.19316 https://arxiv.org/html/2607.19316
arXiv:2607.19316v1 Announce Type: new
Abstract: In the primate visual system, center-preferring cortical populations have higher spatial resolution and overlap face- and word-selective regions while periphery-preferring populations have lower spatial resolution and overlap scene-selective regions. This "eccentricity bias" may reflect differential task-relevance: central vision may better support fine-grained tasks like face recognition and reading, while peripheral vision may better support scene understanding. To test whether eccentricity-dependent coding can emerge from natural experience, we used egocentric video and eye-tracking data from the Visual Experience Dataset (VEDB). We trained ResNet-18 models using contrastive learning (SimCLR) on frames modified to isolate different eccentricities (gaze-contingent fovea-only crops, periphery-only crops, and periphery-only crops with a NeuroFovea transform applied). We evaluated downstream task performance and model alignment with human fMRI data (Natural Scenes Dataset; encoding models). In-domain VEDB frame classification showed systematic differences between fovea- and periphery-only models across categories, indicating differential informativeness across tasks. On downstream classification, VEDB-pretrained models generalized better to scene categorization (Places365) than face recognition (VGGFace2), with fovea-only models stronger on both. Across visual cortex, VEDB-pretrained models matched neural predictivity of models trained on mid-sized non-egocentric datasets (ImageNet-100), suggesting egocentric data supports emergence of cortically-aligned representations. In scene-selective cortex (PPA, RSC), periphery-only models held a small but consistent advantage in explained variance over fovea-only models, suggesting these regions are aligned with peripheral statistics. Together, these results suggest egocentric experience may adaptively constrain cortical information processing.
toXiv_bot_toot
 @memeorandum@universeodon.com
2026-06-28 19:45:33
GOP Sen. Cassidy seeks to explain RFK Jr. confirmation vote for Health and Human Services (Ryan Mancini/The Hill)
https://thehill.com/policy/healthcare/5944508-kennedy-vaccine-views-controversy/
http://www.memeorandum.com/260628/p33#a260628p33
 @arXiv_csHC_bot@mastoxiv.page
2026-08-12 08:22:32
Visual-to-Haptic Augmentation in XR: A Wearable Glove for Perceptual Grounding in Multimodal Interaction
Faisal Mohd, Hamdi Elsaddik, Erhan Baturay Onural, Jihong Zhang, Fedwa Laamarti, Abdulmotaleb El Saddik
https://arxiv.org/abs/2608.10368 https://arxiv.org/pdf/2608.10368 https://arxiv.org/html/2608.10368
arXiv:2608.10368v1 Announce Type: new
Abstract: Extended Reality (XR) systems increasingly deliver high-fidelity visual and auditory experiences, yet tactile perception remains comparatively underutilized as a modality for enriching embodied interaction. This work presents a visual-to-haptic wearable glove and a feature-based visual-to-haptic mapping algorithm that translates spatial and temporal visual features from images and videos into distributed vibrotactile patterns. The proposed method extracts motion, edge, and brightness cues and fuses them into actuator-level intensity maps aligned with a 29-actuator glove arranged in a five-by-seven layout.
The system is implemented through a modular four-layer architecture comprising the XR environment, media content handling, visual-to-haptic processing, and embedded haptic hardware. A within-subject user study (N = 20) compared visual-only interaction with visual-plus-haptic augmentation across texture-based and dynamic video scenarios. Results indicate that tactile augmentation significantly improves perceived realism in dynamic video scenarios and enhances immersion and visual-tactile correspondence across conditions, with stronger and more consistent effects observed for dynamic visual events.
While the current implementation operates in a single-user, offline-synchronized configuration, the findings demonstrate that vision-driven tactile augmentation can function as a perceptual enhancement layer within multimodal XR systems. Such a layer may provide a foundation for future socially enriched XR environments where coherent multisensory grounding supports higher-level interaction and communication.
toXiv_bot_toot