The Federal Communications Commission will vote next month on whether a single company can own broadcast stations that reach more than 39 percent of US TV households.
In a Breitbart op-ed on Wednesday, Republican Chair Brendan Carr announced an August 6th vote to end the national ownership cap rule,
which was intended to prevent one company from dominating the media landscape and incentivize serving local communities.
Carr argued the rise of social media and streaming plat…
City Lives III 🔃
城市人生 III 🔃
📷 Pentax 6x7
🎞️ LUCKY SHD 400 (6x7)
If you like my work, Support by buying me a coffee or a roll of film from
PayPal https://www.paypal.com/paypalme/ydcdingsite
Wise
🔧 Size runs by rows with chunk, or cap the total job count with maxJobs. tries, backoff, throttle, delay and queue routing can be set per call or once in config/queue-sql.php
🎨 dryRun() previews the plan — operation, table, job count, ranges, estimated rows — without dispatching anything
Product sets in sets of returns and positivity of symmetric ergodic averages
Vitaly Bergelson, Sa\'ul Rodr\'iguez-Mart\'in
https://arxiv.org/abs/2608.02873 https://arxiv.org/pdf/2608.02873 https://arxiv.org/html/2608.02873
arXiv:2608.02873v1 Announce Type: new
Abstract: We study sets of (measurable) returns in countable groups $G$, namely sets of the form $\{g\in G:\mu(A\cap T_gA)>0\}$ arising from measure-preserving actions. Extending a result of Bergelson, we show that sets of returns in $G\times G$ contain subsets of the form $B\times B$, where $B$ is large with respect to suitable notions of largeness that remain meaningful even for non-amenable groups. As a consequence, if $G$ is amenable, then every sufficiently large subset $A\subseteq G\times G$ satisfies $B\times B\subseteq AA^{-1}$ for some large set $B\subseteq G$.
We also investigate when sets of returns in $G$ contain product sets $BB$ with $B$ large. In contrast with the Cartesian-product phenomenon above, this problem is considerably subtler in non-abelian groups and is closely connected to `symmetric correlation functions', namely functions of the form $g\mapsto \mu(T_g^{-1}A\cap T_gA)$. We use this connection to show that, for broad classes of amenable groups - including finitely generated nilpotent groups and certain solvable non-nilpotent groups, every sufficiently large set $A\subseteq G$ contains a large subset $B$ satisfying $BB\subseteq AA^{-1}$.
Finally, we establish polynomial analogues of these results for finitely generated nilpotent groups, extending earlier work of Bergelson and Ruzsa.
toXiv_bot_toot
GateTruth: Auditing the Rigor of RTL Design Benchmarks via Mutation Testing
Meet Bhadra
https://arxiv.org/abs/2608.12635 https://arxiv.org/pdf/2608.12635 https://arxiv.org/html/2608.12635
arXiv:2608.12635v1 Announce Type: new
Abstract: Benchmarks for evaluating large language models on register-transfer-level (RTL) hardware design have proliferated rapidly, yet none reports having applied mutation testing, an established hardware-verification technique for quantifying testbench quality, to ask whether its own testbenches are trustworthy. A testbench that never fails is not evidence of a correct design; it may simply never stimulate the logic that is actually broken. We introduce GateTruth, a mutation-testing engine and methodology for auditing RTL benchmark testbench rigor: inject a deterministic, seeded set of semantic mutants into a reference design and measure what fraction the testbench catches.
We validate the methodology against our own 68-task, dual-track reference suite -- 60 specification-to-RTL generation tasks and 8 agentic-repair tasks, scored through a pinned, deterministic synthesis-to-timing flow with correctness enforced as a strict gate -- certifying that 46 of 60 Track A testbenches kill at least 95% of injected mutants under sequential, reproducible execution; we disclose why the other 14 do not, including a Goodhart effect on testbenches revised to pass this gate. We then point the same engine, unmodified, at RTLLM v2.0, a widely adopted external benchmark: of 46 auditable designs, 72% fall below the 95% floor our own suite is held to, and three score 0% outright.
A comparable audit of NVIDIA's CVDP benchmark is structurally impossible: its public release withholds reference solutions, removing the golden RTL mutation testing requires. Auditing our own instrument also surfaced a second finding: an initially uniform 4096-token output cap silently truncated three of seven evaluated models, and re-running at 16,384 tokens moved one model from fifth place to first. We argue mutation-kill certification should become a standard reporting requirement for RTL-generation benchmarks generally.
toXiv_bot_toot
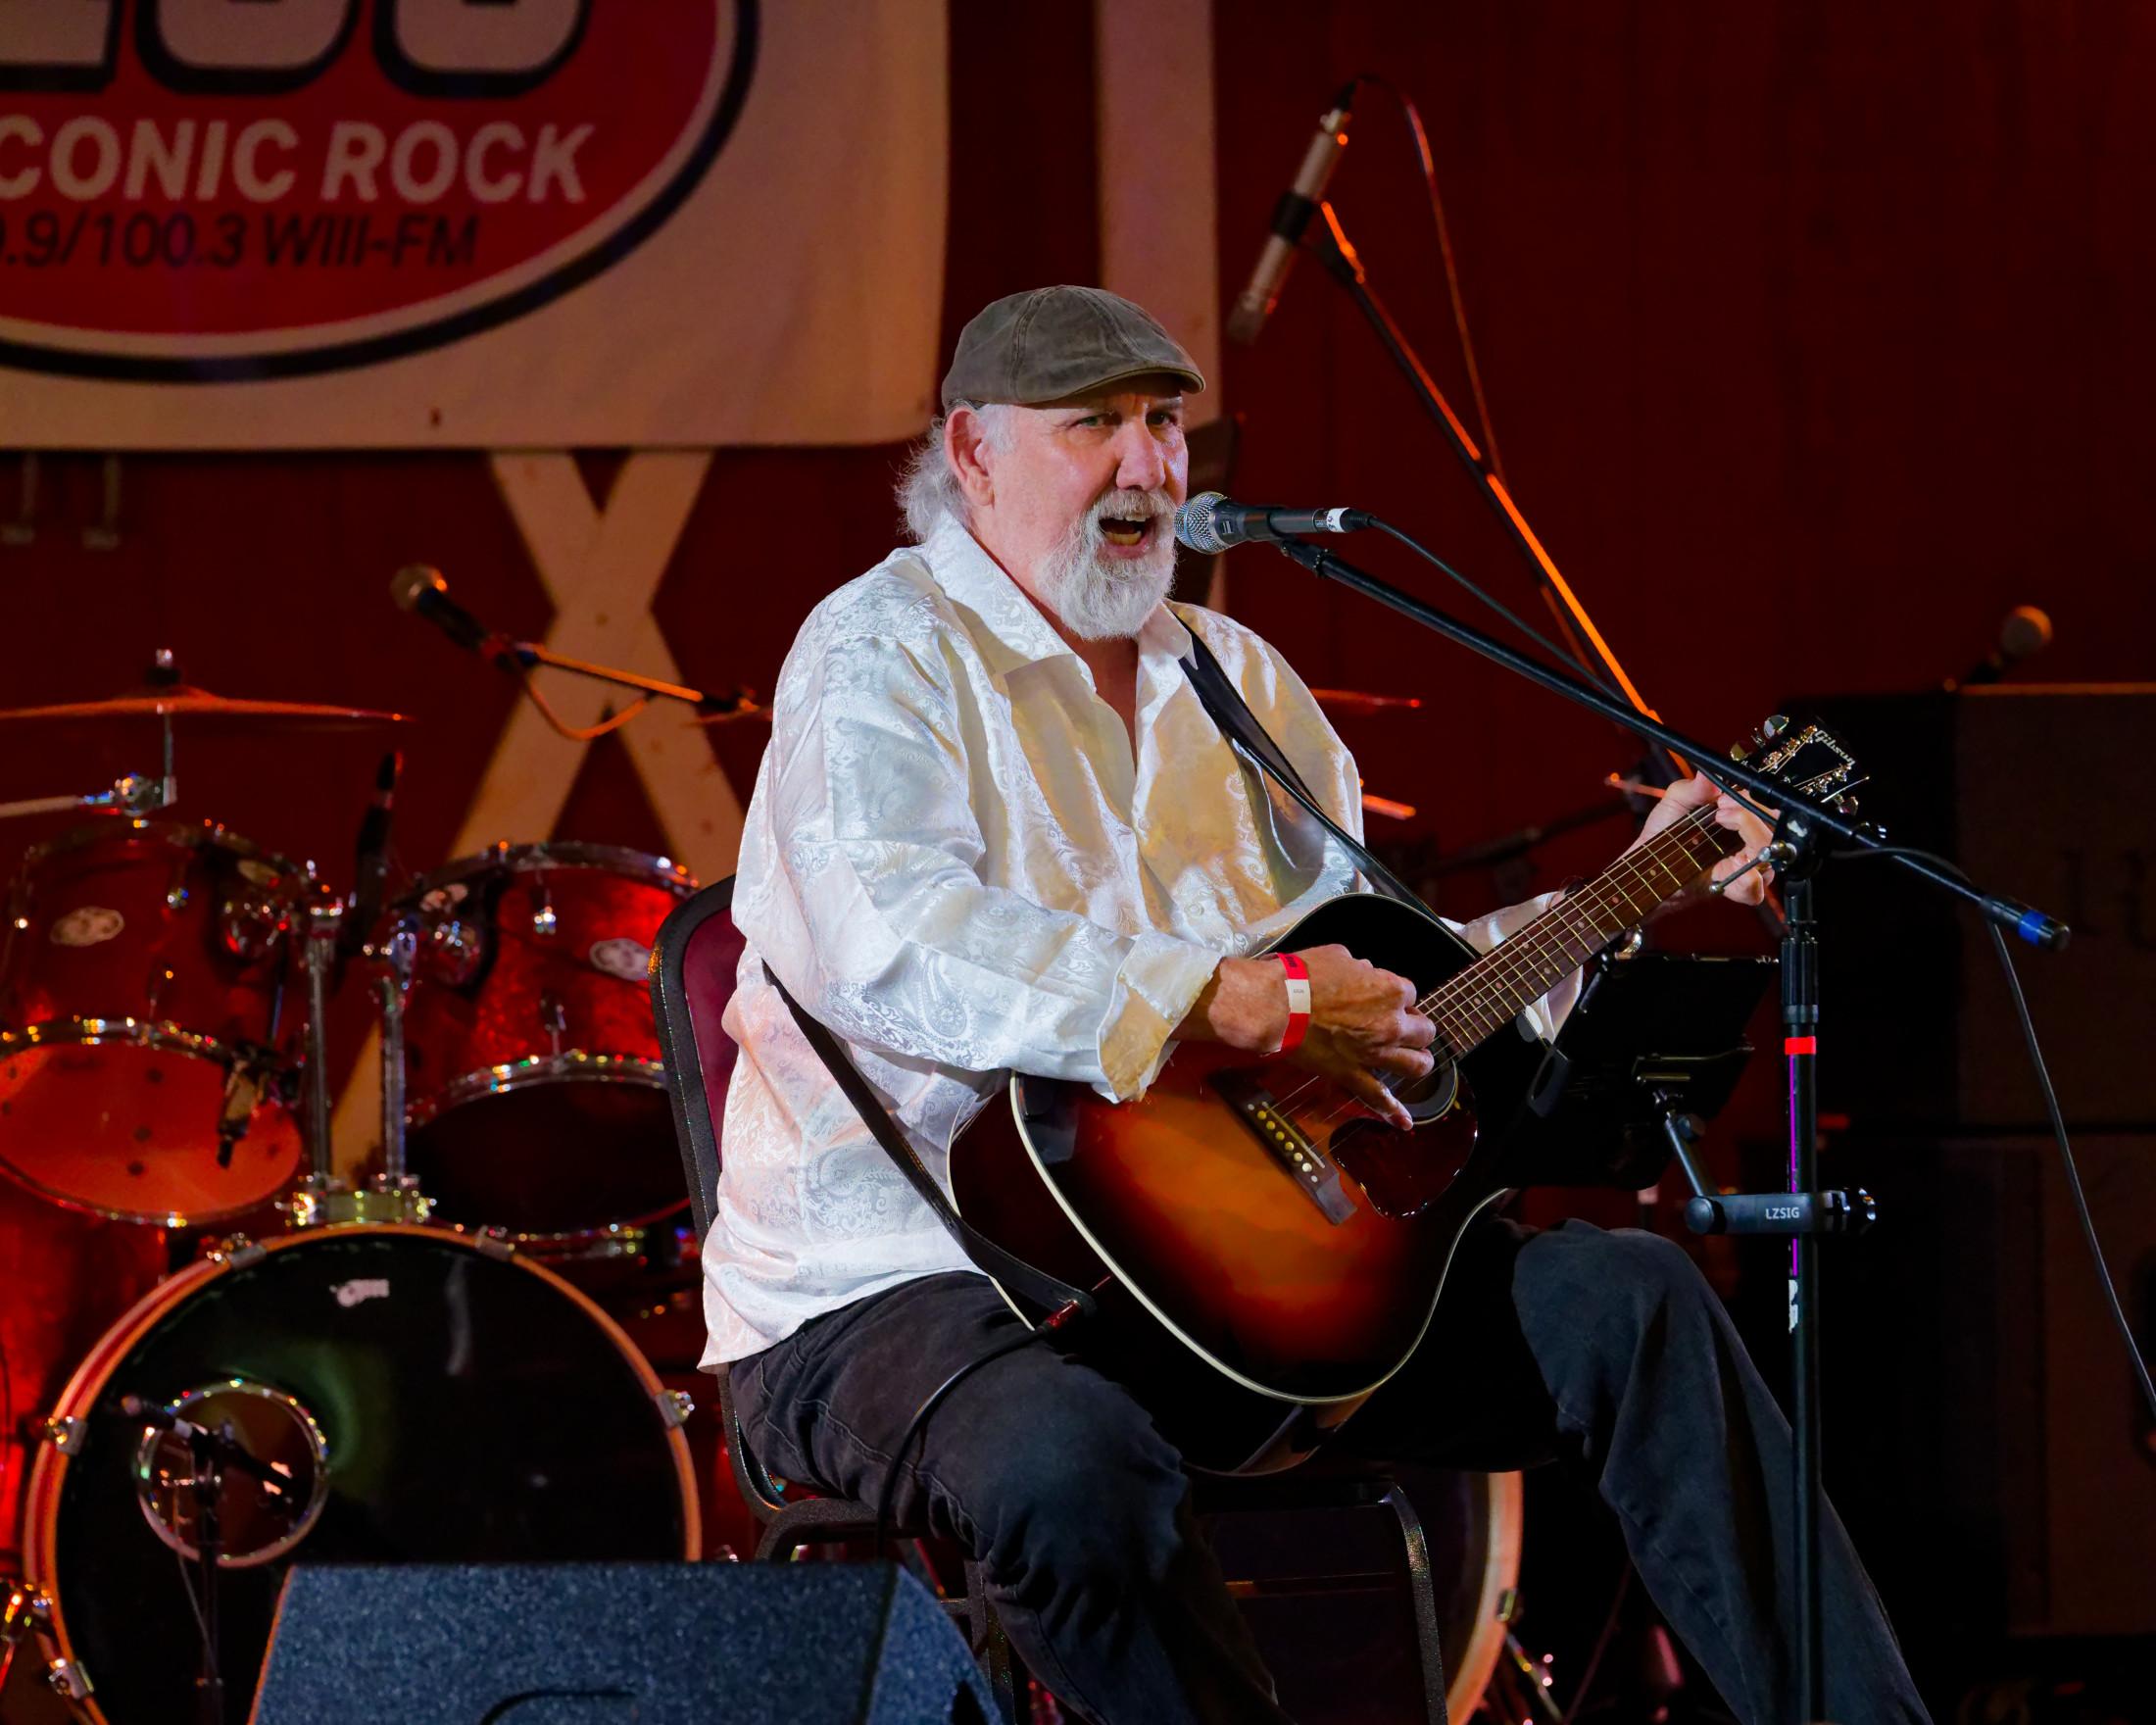
Jim Van Duesen opened for Dio Day 20265
#photo #photography #portrait #music
 @cdarwin@c.im