@Techmeme@techhub.social
2026-10-07 20:56:04
OpenAI says GPT-6 in ChatGPT's Chat tab is powered by GPT-6 Sol for Plus, Pro, Business, and Enterprise tiers and GPT-6 Luna for Free and Go tiers (@openai)
https://x.com/openai/status/2107895006350791071
@Techmeme@techhub.socialOpenAI says GPT-6 in ChatGPT's Chat tab is powered by GPT-6 Sol for Plus, Pro, Business, and Enterprise tiers and GPT-6 Luna for Free and Go tiers (@openai)
https://x.com/openai/status/2107895006350791071
 @Mediagazer@mstdn.social
Bill Simmons is facing backlash for using OpenAI's ChatGPT to simulate film reviews from the late critic Roger Ebert on his podcast; OpenAI runs ads on the show (Benjamin Mullin/New York Times)
https://www.nytimes.com/2026/0…
 @newsie@darktundra.xyz
'Tell Everyone:' A Man Died by Suicide After Talking to ChatGPT. His Former Partner Wants to Warn the World About AI https://www.404media.co/austin-gordon-chatgpt-suicide-openai-lawsuit/
 @ErikJonker@mastodon.social
For me this age of AI is the time we should appreciate less polished handwritten texts for their authenticity. I see this happening during selection of job applications.
https://www.theguardian.com/books/ng-interactive/2026…
 @NFL@darktundra.xyz
Eagles coach Nick Sirianni adjusting to offseason ... https://www.espn.com/nfl/story/_/id/49410531/philadelphia-eagles-coach-nick-sirianni-adjust-offseason-changes-chat-gpt-pop-quizzes
 @arXiv_csCR_bot@mastoxiv.page
Evaluating Large Language Models for Symbolic Security Protocol Analysis
Paolo Modesti, Syed Ahmed, Ioannis Sfyrakis, Derek Enodolomwanyi
https://arxiv.org/abs/2607.20712 https://arxiv.org/pdf/2607.20712 https://arxiv.org/html/2607.20712
arXiv:2607.20712v1 Announce Type: new
Abstract: Security protocol verification relies on formal tools such as ProVerif and OFMC. This study evaluates whether Large Language Models (LLMs) can perform comparable analysis. We test GPT and DeepSeek in chat and reasoning modes over three runs on 130 obfuscated AnB/AnBx protocols covering 388 security goals, scored against ProVerif and OFMC. Chat models reach 69 to 81% recall at precision below 31%. Reasoning models reverse this trade-off, reaching 66.5% precision for GPT and 45.4% for DeepSeek, but detect just over half the attacks. DeepSeek's two modes share one underlying model, so the comparison isolates reasoning itself, which raises precision from 27.2% to 45.4%. The GPT contrast spans a model-version change and is only suggestive. All models perform worst on authentication goals: reasoning models detect well under half of injective and non-injective agreement attacks, whereas chat models over-flag them at low precision. Confidentiality is the exception, with F1 up to 95.7% in reasoning mode. Verdicts are unstable across runs, identical on 89.7% of goals for GPT but 74.0% for DeepSeek. Self-reported confidence is uniformly high yet shows no meaningful correlation with correctness. On this benchmark LLMs do not match formal verification, but may serve, at best, as pre-screening filters.
toXiv_bot_toot
@Techmeme@techhub.socialOpenAI launches a ChatGPT Health integration with Epic's EHR system and a new Healthcare Public Data plug-in that can fetch info from sources including PubMed (Ivan Mehta/TechCrunch)
https://techcrunch.com/2026/09/01/chatgpt-h…
 @pre@boing.world
If anyone working on a frontier technical problem discusses that problem with Chat GPT, telling it their ideas to refine them, then OpenAI will quickly claim those ideas for themselves, and publish that their robot made them!
AI will be involved in every future discovery! It will win in the race to publication against those who told it their ideas in the first place.
Don't tell the robots your secrets, they do not keep secrets from their owners.
#ai #plagerism
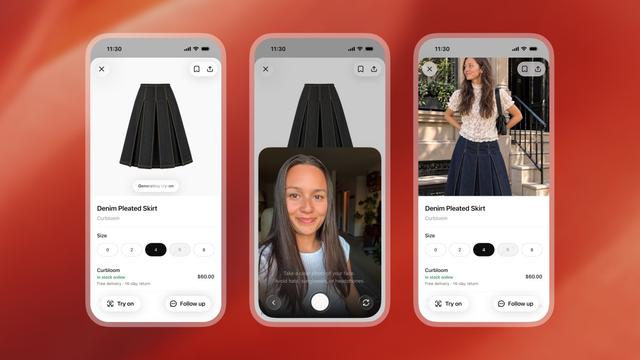
@Techmeme@techhub.socialOpenAI launches two ChatGPT shopping features: a virtual try-on tool for clothing and accessories, and a Favorites feature to save products to a user's Library (Sarah Perez/TechCrunch)
https://techcrunch.com/2026/10/01/chatgpt-can-now-virtually-try-on-…
 @arXiv_qbioOT_bot@mastoxiv.page
Orientation Reading by Production Vision-Language Models on Optotype Charts: A Controlled Multi-Model Evaluation Across Reasoning Modes, Prompts, and Access Modalities
Shahryar Wasif, Avneek Sandhu, Bin Hu
https://arxiv.org/abs/2607.16595 https://arxiv.org/pdf/2607.16595 https://arxiv.org/html/2607.16595
arXiv:2607.16595v1 Announce Type: new
Abstract: OBJECTIVES: Vision-language models are increasingly used to interpret medical and everyday images through consumer chat interfaces, yet their ability to read orientation - the single perceptual operation tested by the tumbling-E acuity optotype - is poorly characterized on the surfaces through which they are actually used. METHODS: We evaluated four production vision-language models (referred to as Claude, GPT, GROK, and Gemini) through their consumer chat interfaces on a locked set of seven optotype charts: four uniform tumbling-E charts (one per cardinal orientation), two mixed-orientation tumbling-E charts, and one Snellen letter chart as a specificity control. Each model was run in two reasoning modes (Fast and Thinking) under two prompt variants (with and without an explicit orientation-decoding rule) by up to three operators. The corpus comprised 920 scoreable trials and 50,420 glyph judgements. The primary outcome was glyph-level accuracy against the chart's designed orientation, summarized with Wilson 95% confidence intervals. RESULTS: Accuracy ranged from 43.0% to 97.0% across models on identical charts, and the strongest model depended on reasoning mode (GPT 97.0% in Fast mode; GROK 96.6% in Thinking mode). Errors were not random but collapsed onto a model-specific attractor direction. Models were 96-100% internally self-consistent yet ranged widely in accuracy, dissociating reliability from validity. An answer-key-free ensemble-consensus estimate tracked accuracy closely (r = 0.998). For one model, consumer-interface accuracy fell 25-27 points below programmatic access, almost entirely on a single orientation. CONCLUSIONS: A single accuracy figure conceals clinically relevant, orientation-specific failure modes; vision-language models should be evaluated along multiple axes and on the deployment surface before image-interpretation outputs are trusted.
toXiv_bot_toot
 @Life_is@no-pony.farm
In einem ARD-Podcast sagt der Moderator in Bezug auf eine seltene Krankheit, da musste ich auch erst mal bei Dr. Google nachsehen. Es ist ja vielleicht schön, dass er nicht in Chat GPT nachgesehen hat. Und es ist doof, dass er nicht dort nachgesehen hat, wo er hätte nachsehen sollen in Wikipedia. Aber das er aus der ehemaligen Such-Maschine Google auch noch einen Dr. macht. ja, das ist krsnk.
@life_is@no-pony.farmIn einem ARD-Podcast sagt der Moderator in Bezug auf eine seltene Krankheit, da musste ich auch erst mal bei Dr. Google nachsehen. Es ist ja vielleicht schön, dass er nicht in Chat GPT nachgesehen hat. Und es ist doof, dass er nicht dort nachgesehen hat, wo er hätte nachsehen sollen in Wikipedia. Aber das er aus der ehemaligen Such-Maschine Google auch noch einen Dr. macht. ja, das ist krsnk.
 @kurtsh@mastodon.social
Microsoft 365 Copilot for #GCC / #Government just had a massive wave of announcements:
✅ OpenAI’s GPT-5.6
✅ Memory & Personalization
✅ Native editing with Copilot in Word, Excel & PowerPoint
✅ Copilot Chat (Basic) in Outlook with lexical search for ALL email, contacts, meetings
✅ Copilot Notebooks with native integration in OneNote
✅ Copilot in Forms
Check out the Public Sector blog post here:
✅ What's Next in #Microsoft 365 #Copilot for Government
https://techcommunity.microsoft.com/blog/publicsectorblog/whats-next-in-microsoft-365-copilot-for-government/4555457